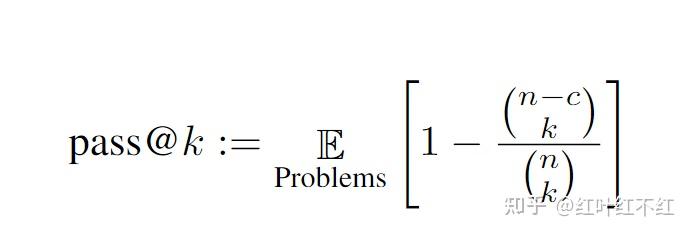Showing 120 of 120on this page. Filters & sort apply to loaded results; URL updates for sharing.120 of 120 on this page
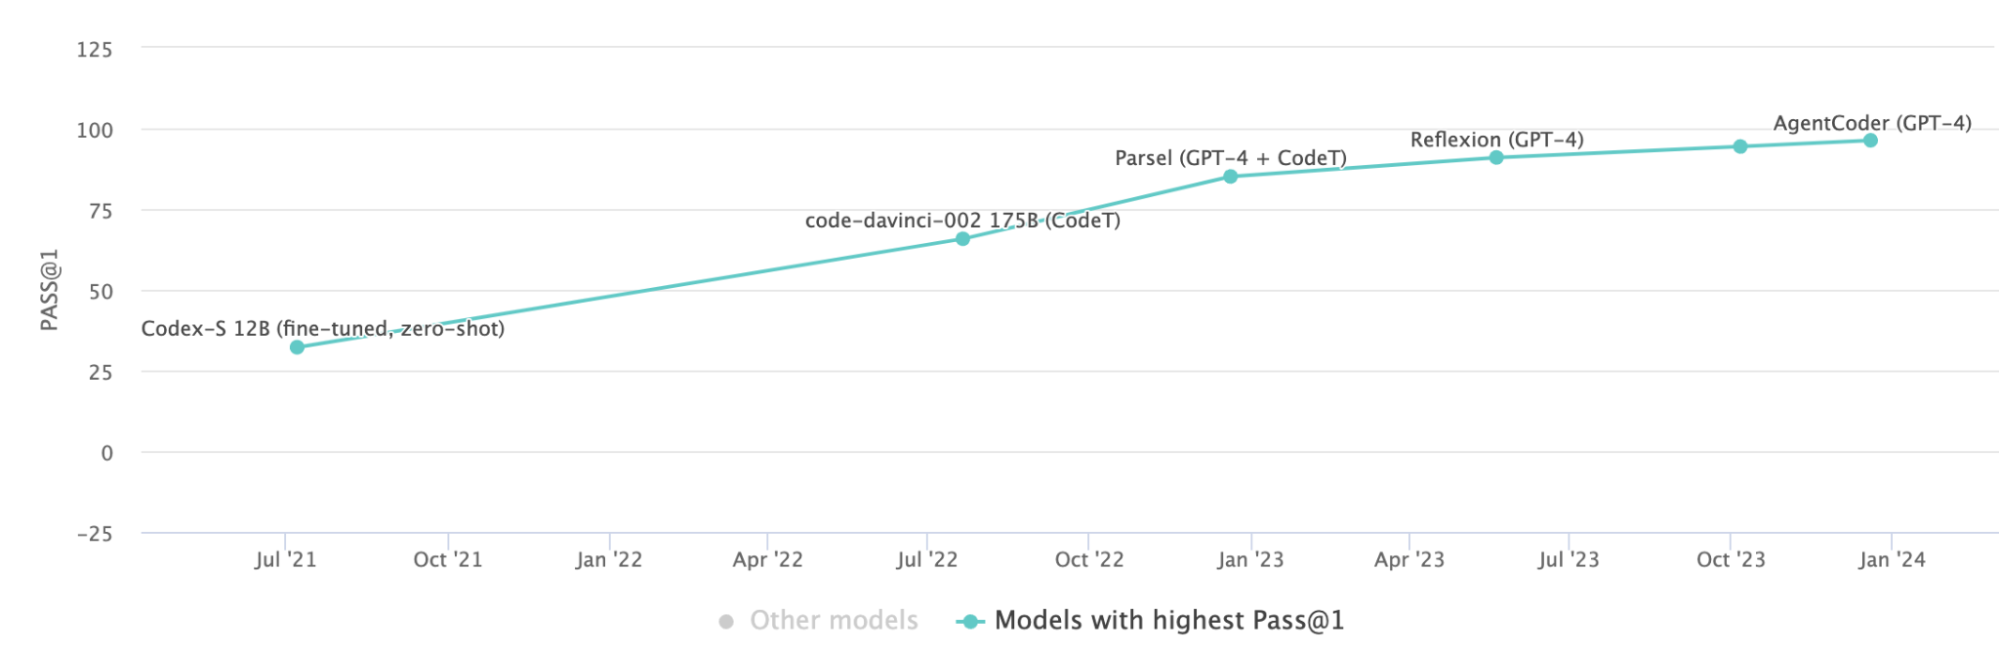
From HumanEval to SWE-bench | Rui Zheng
HumanEval Benchmark — Klu
HumanEval - 知乎
HumanEval and LLM Performance Analysis - YouTube
HumanEval Dataset | openai/human-eval | DeepWiki
HumanEval Benchmark: Evaluating LLM Code Generation Capability
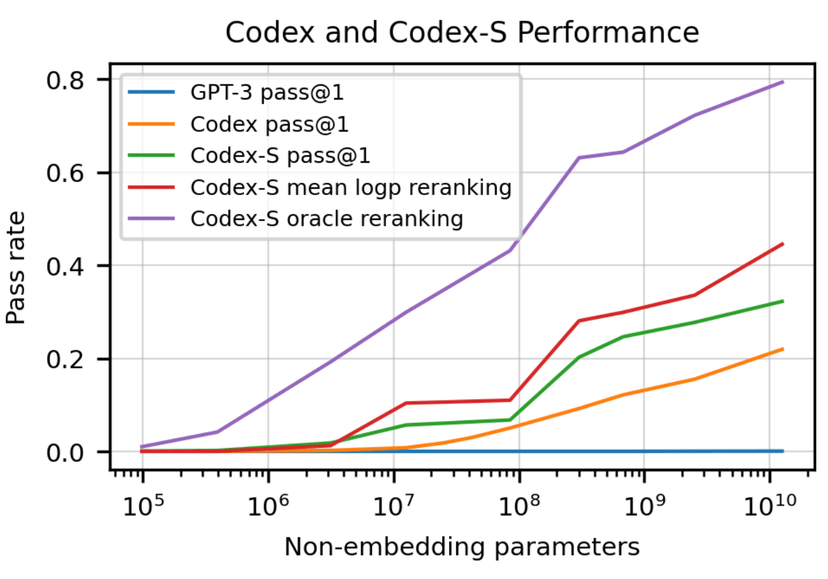
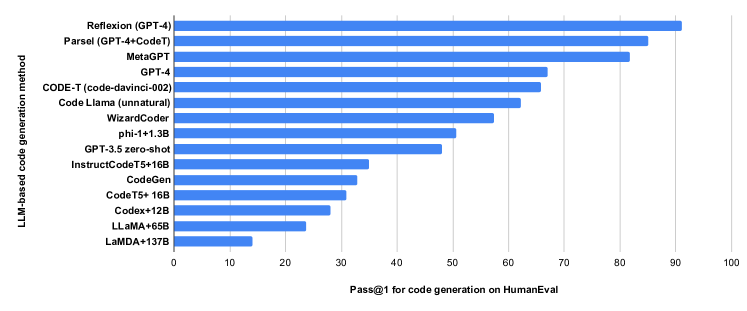
Results on the HumanEval dataset. | Download Scientific Diagram
HumanEval Pro and MBPP Pro: Evaluating Large Language Models on Self ...
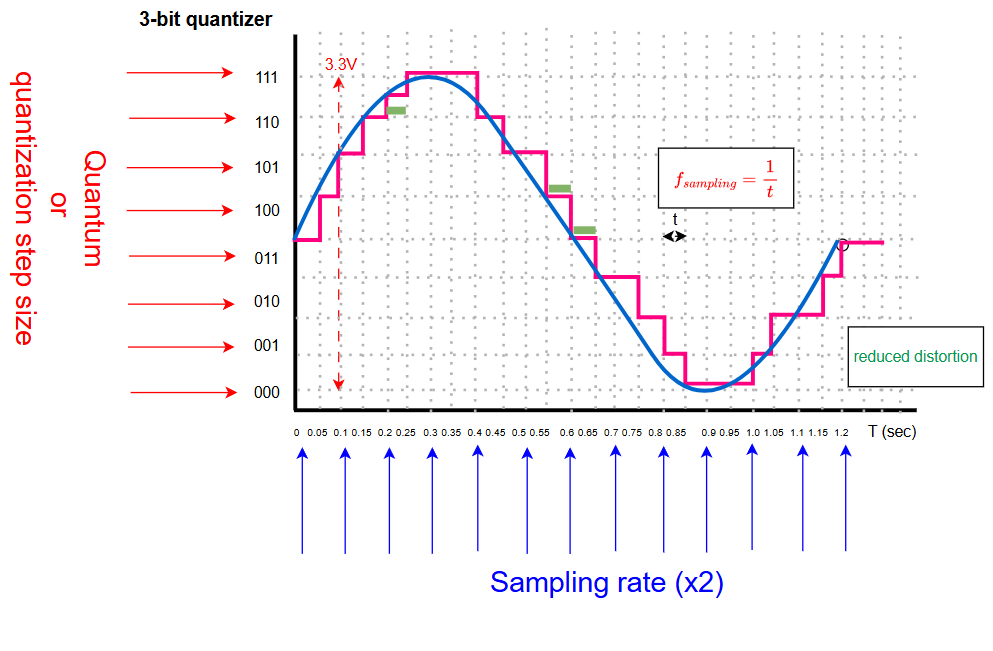
Image Quantization | PPTX
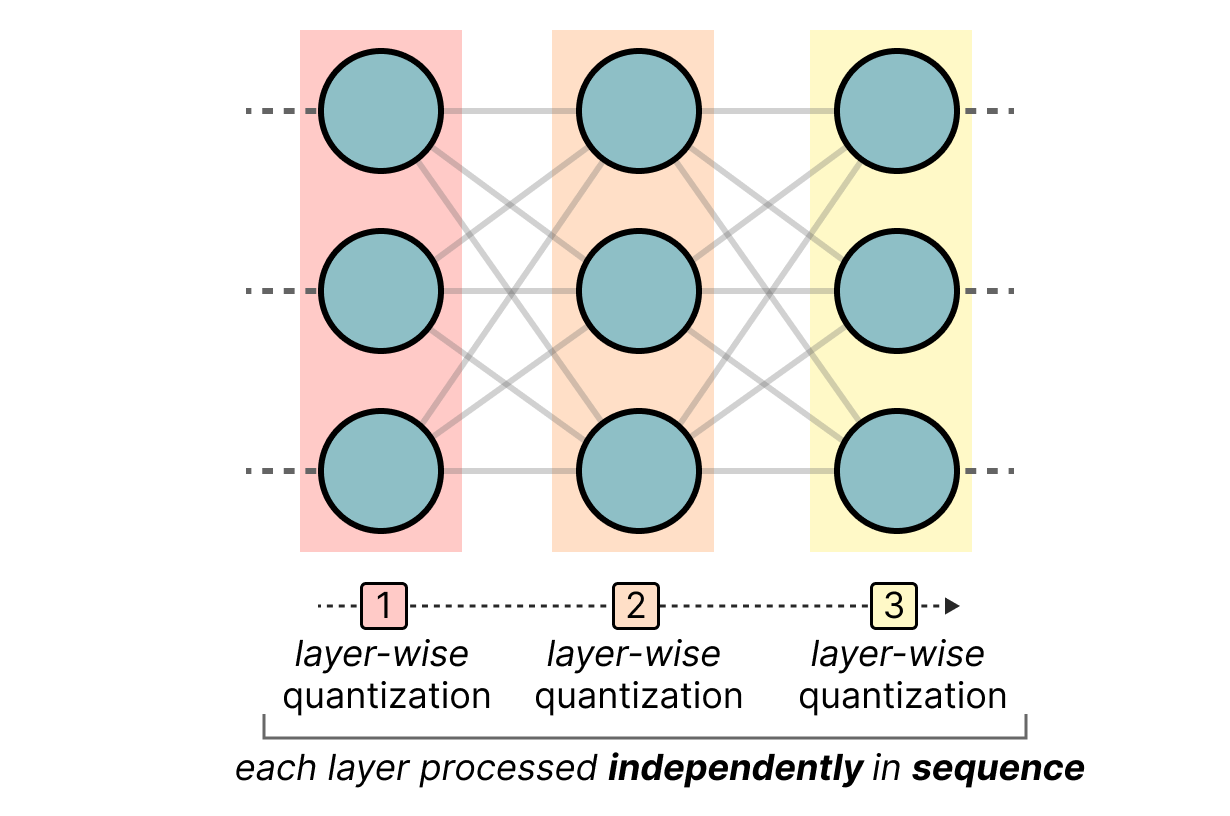
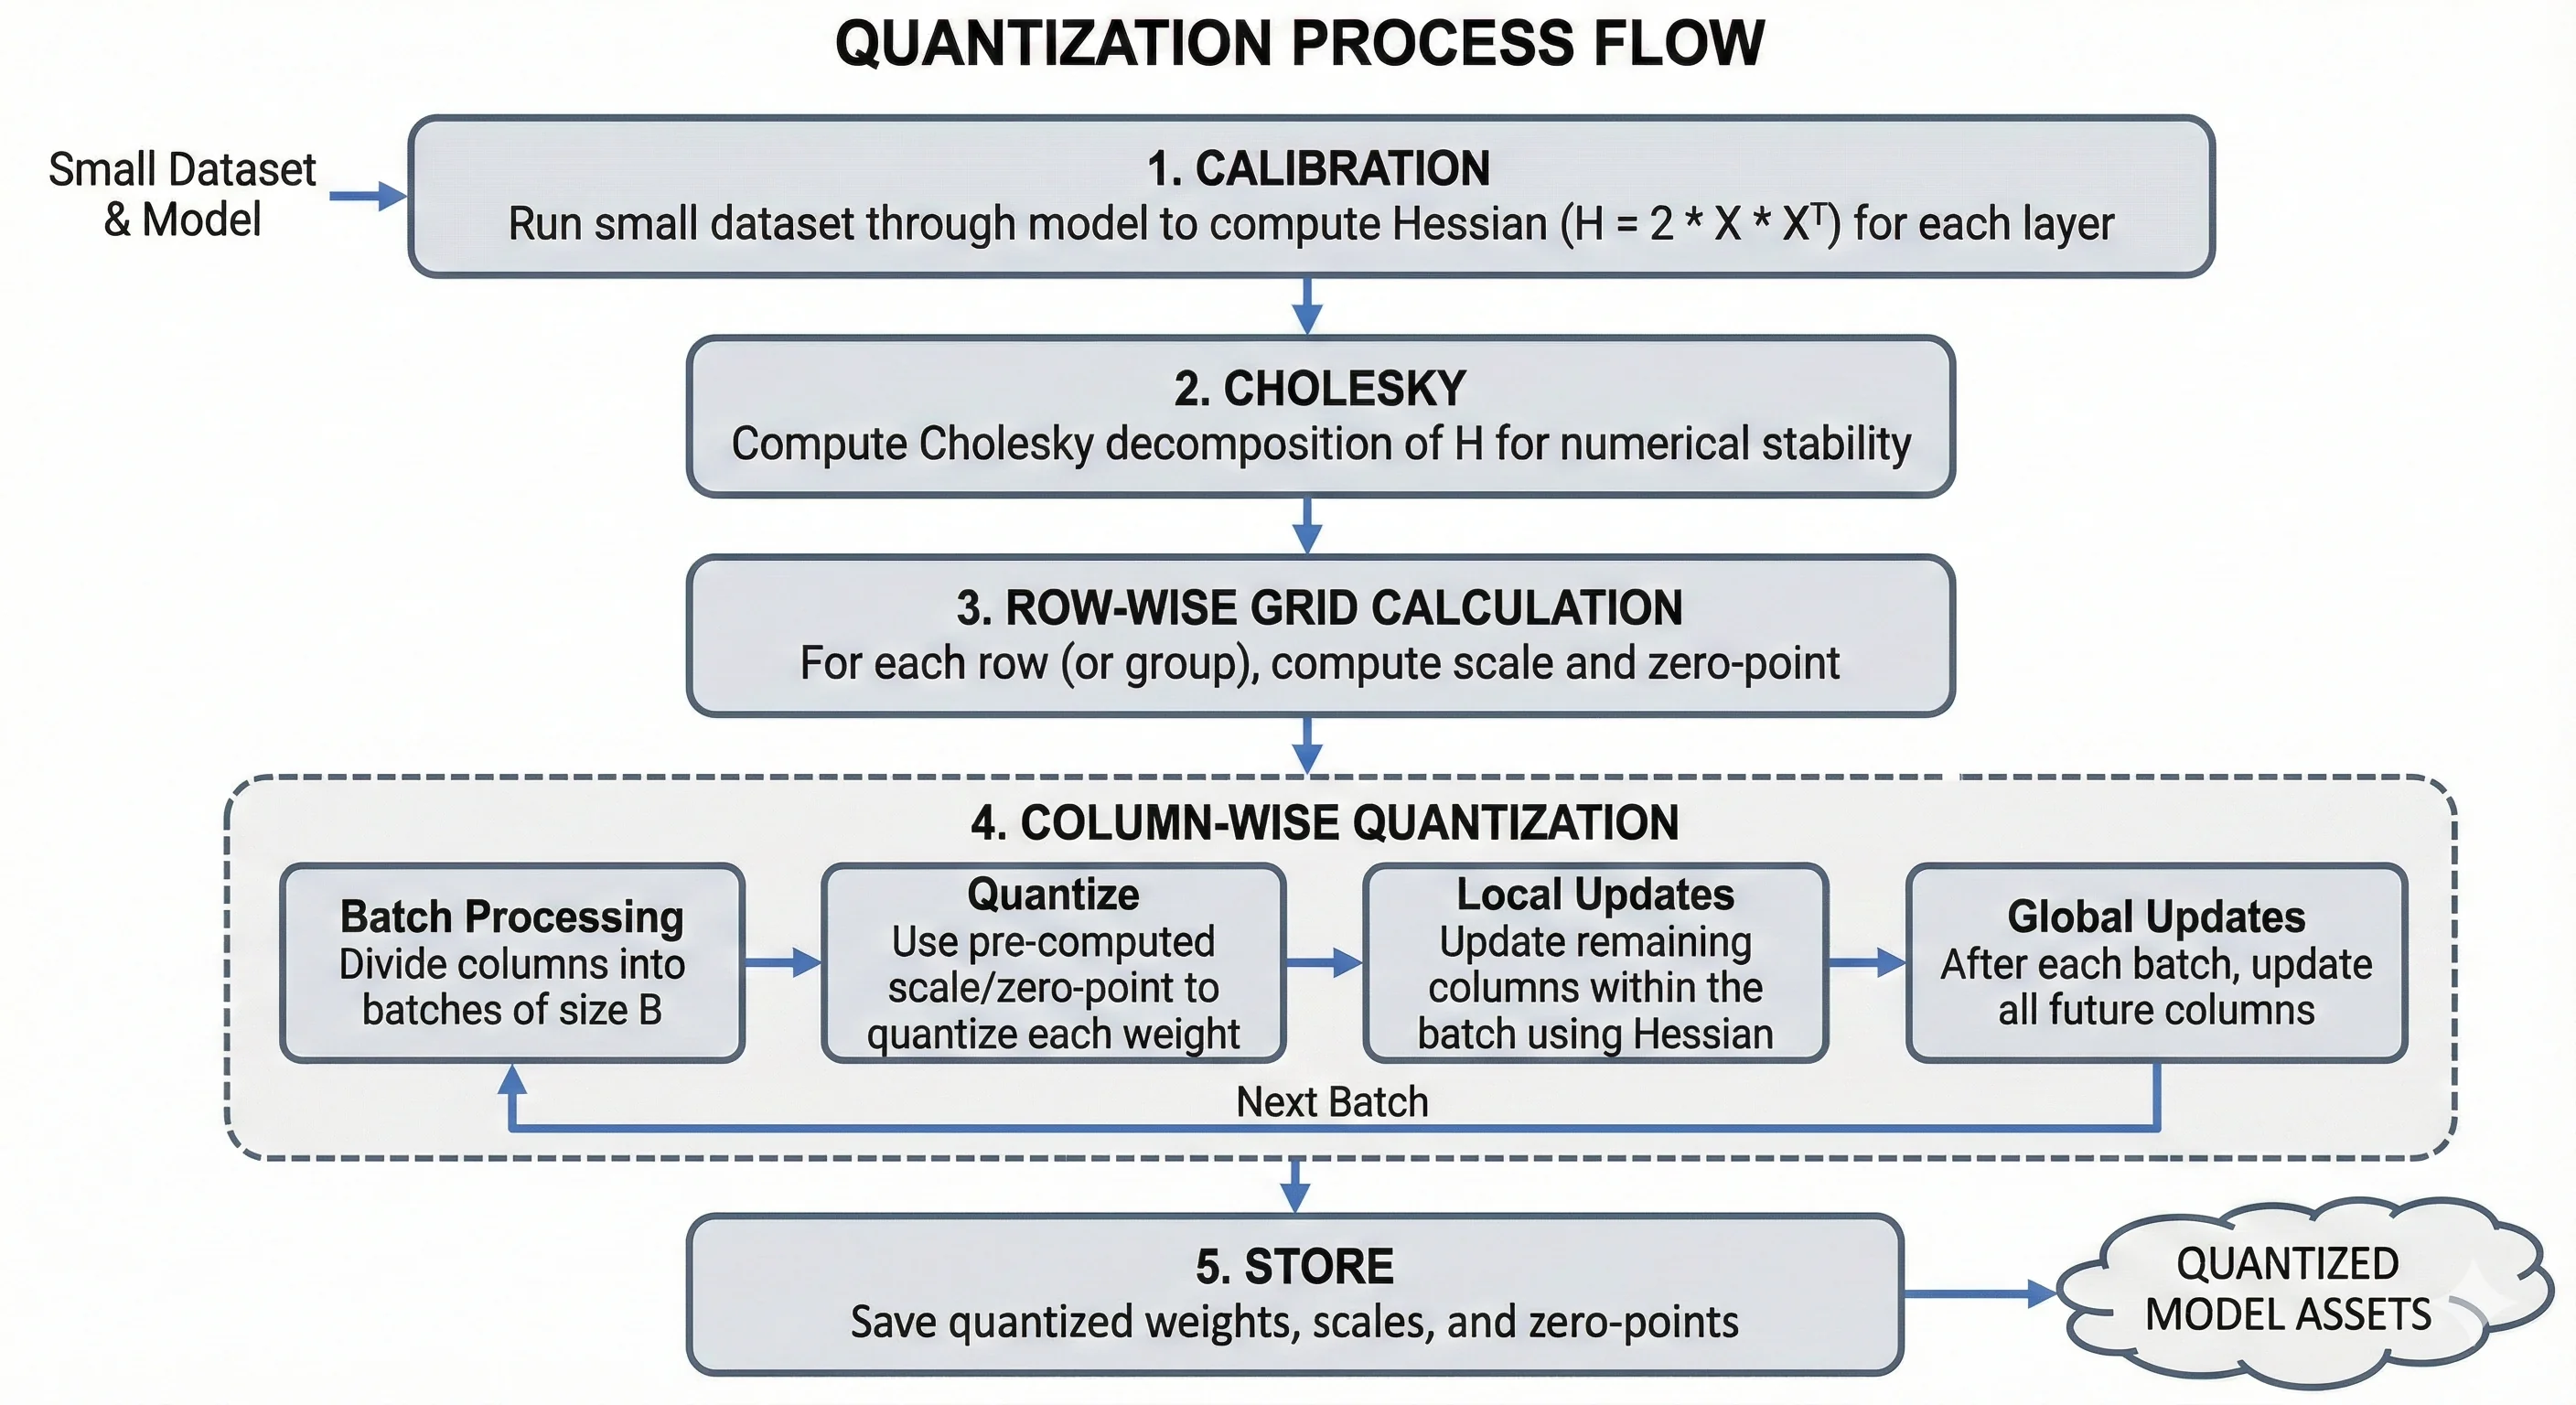
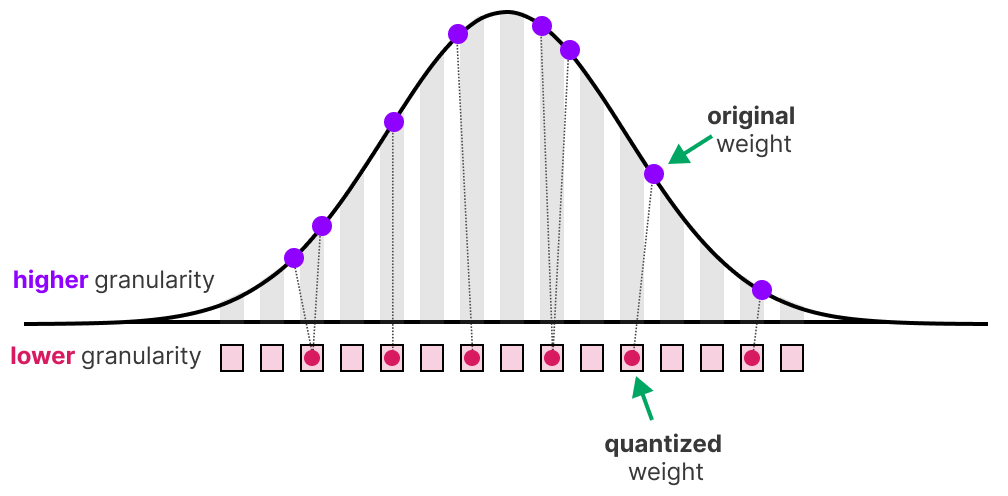
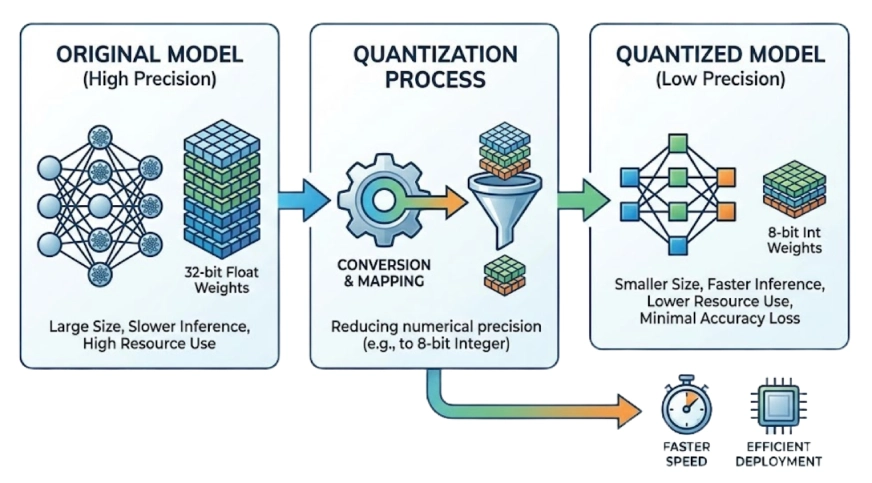
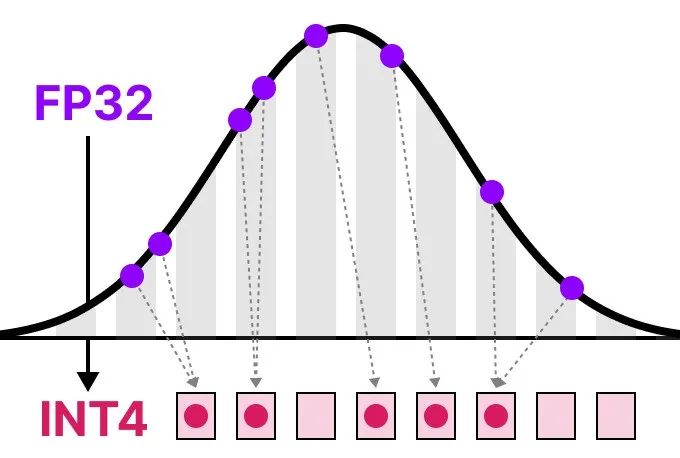
A Visual Guide to Quantization - by Maarten Grootendorst
HumanEval performance of a 350M model on different training sets ...
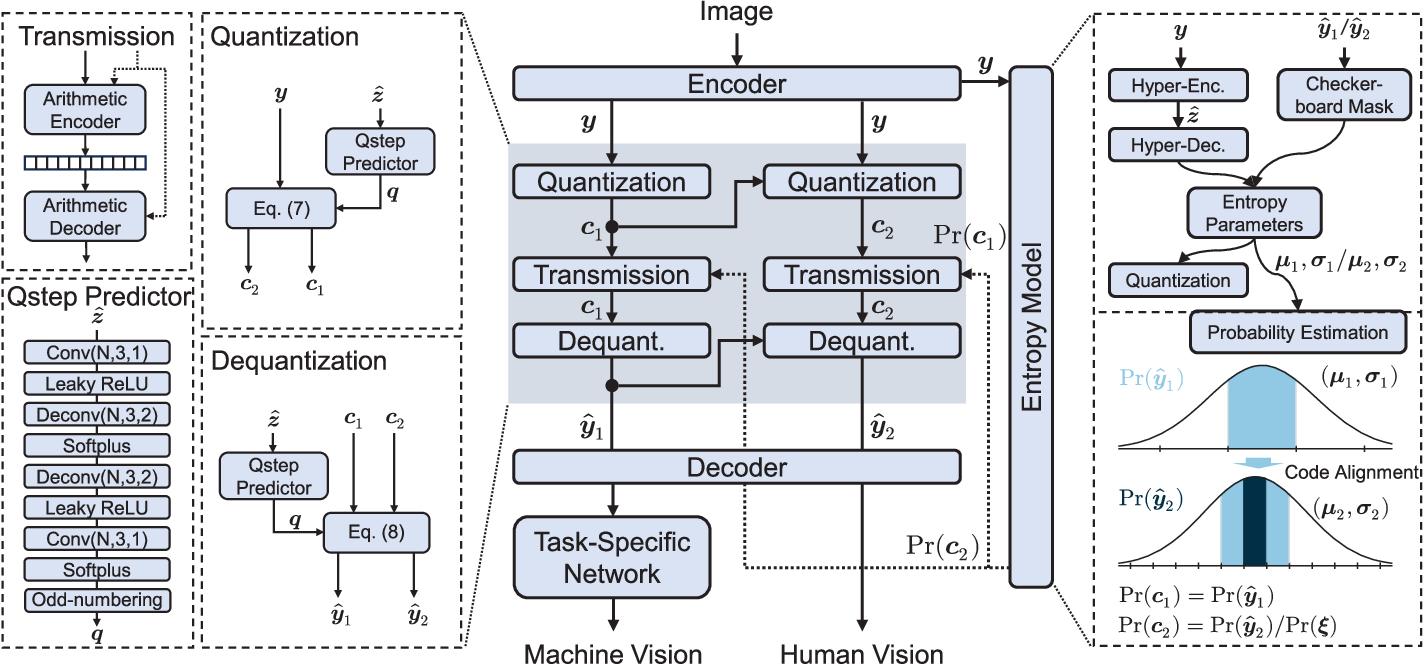
Figure 3 from Task–Adapted Learnable Embedded Quantization for Scalable ...
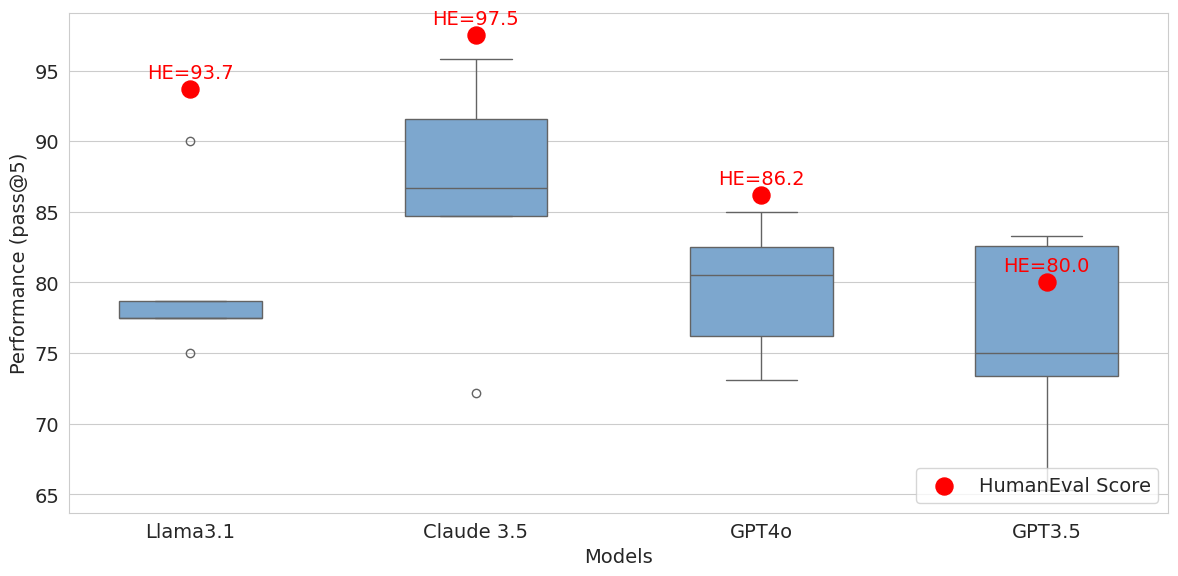
HumanEval as an accurate code benchmark : r/LocalLLaMA
The Complete Guide to LLM Quantization with vLLM: Benchmarks & Best ...
HumanEval Benchmark Comparison with models of similar size(3B) : r ...
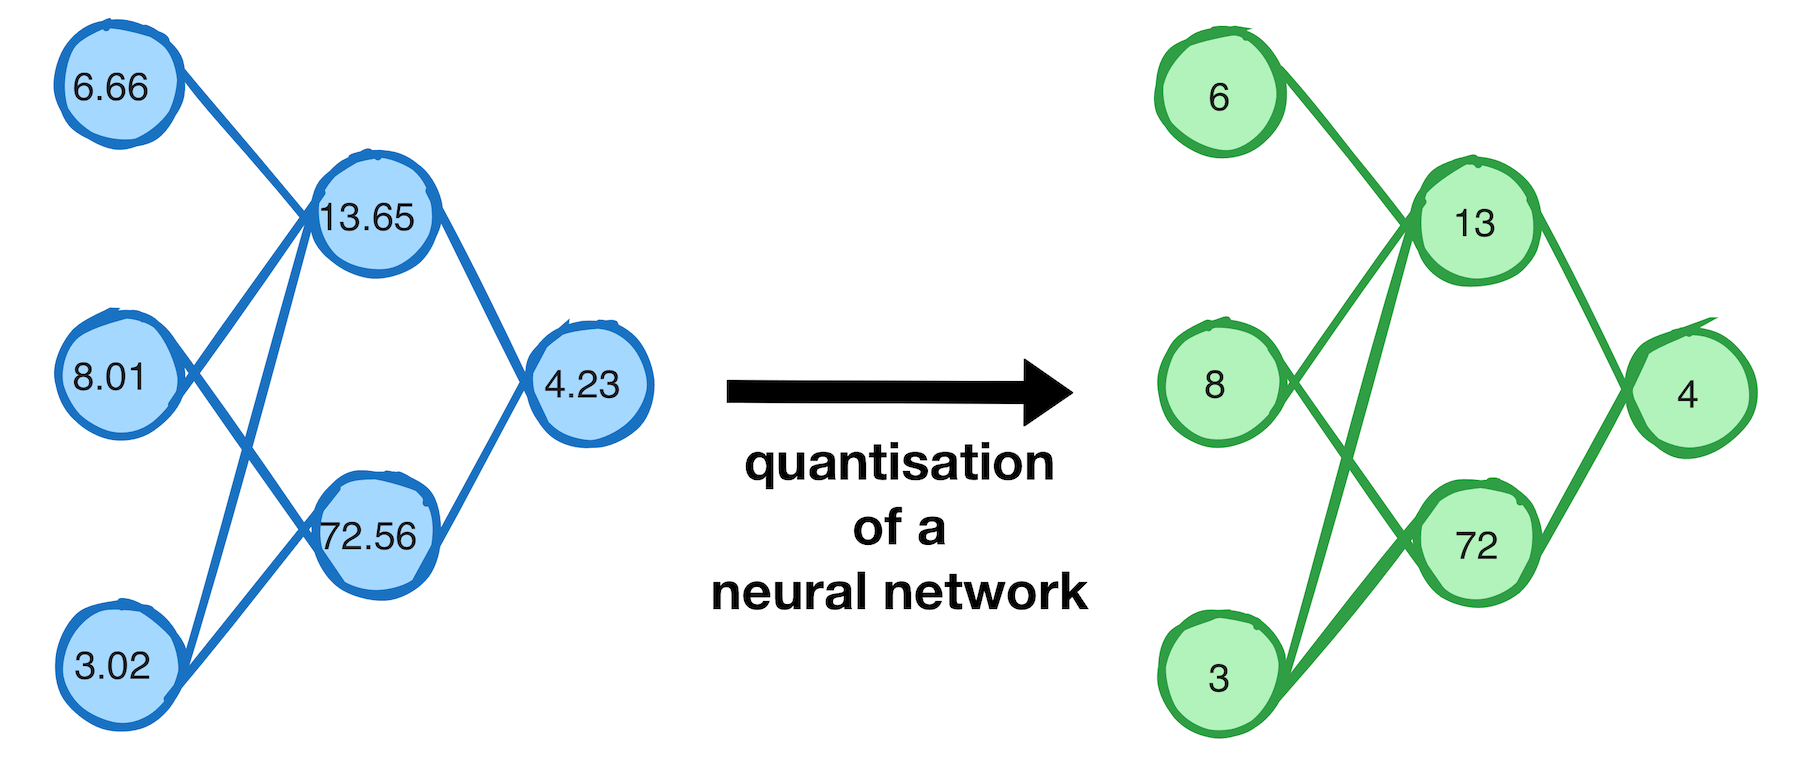
Neural Network Quantization Paper – ZMIF
Results on the HumanEval dataset showing the zero-shot transferability ...
Comparing HumanEval vs. EvalPlus - YouTube
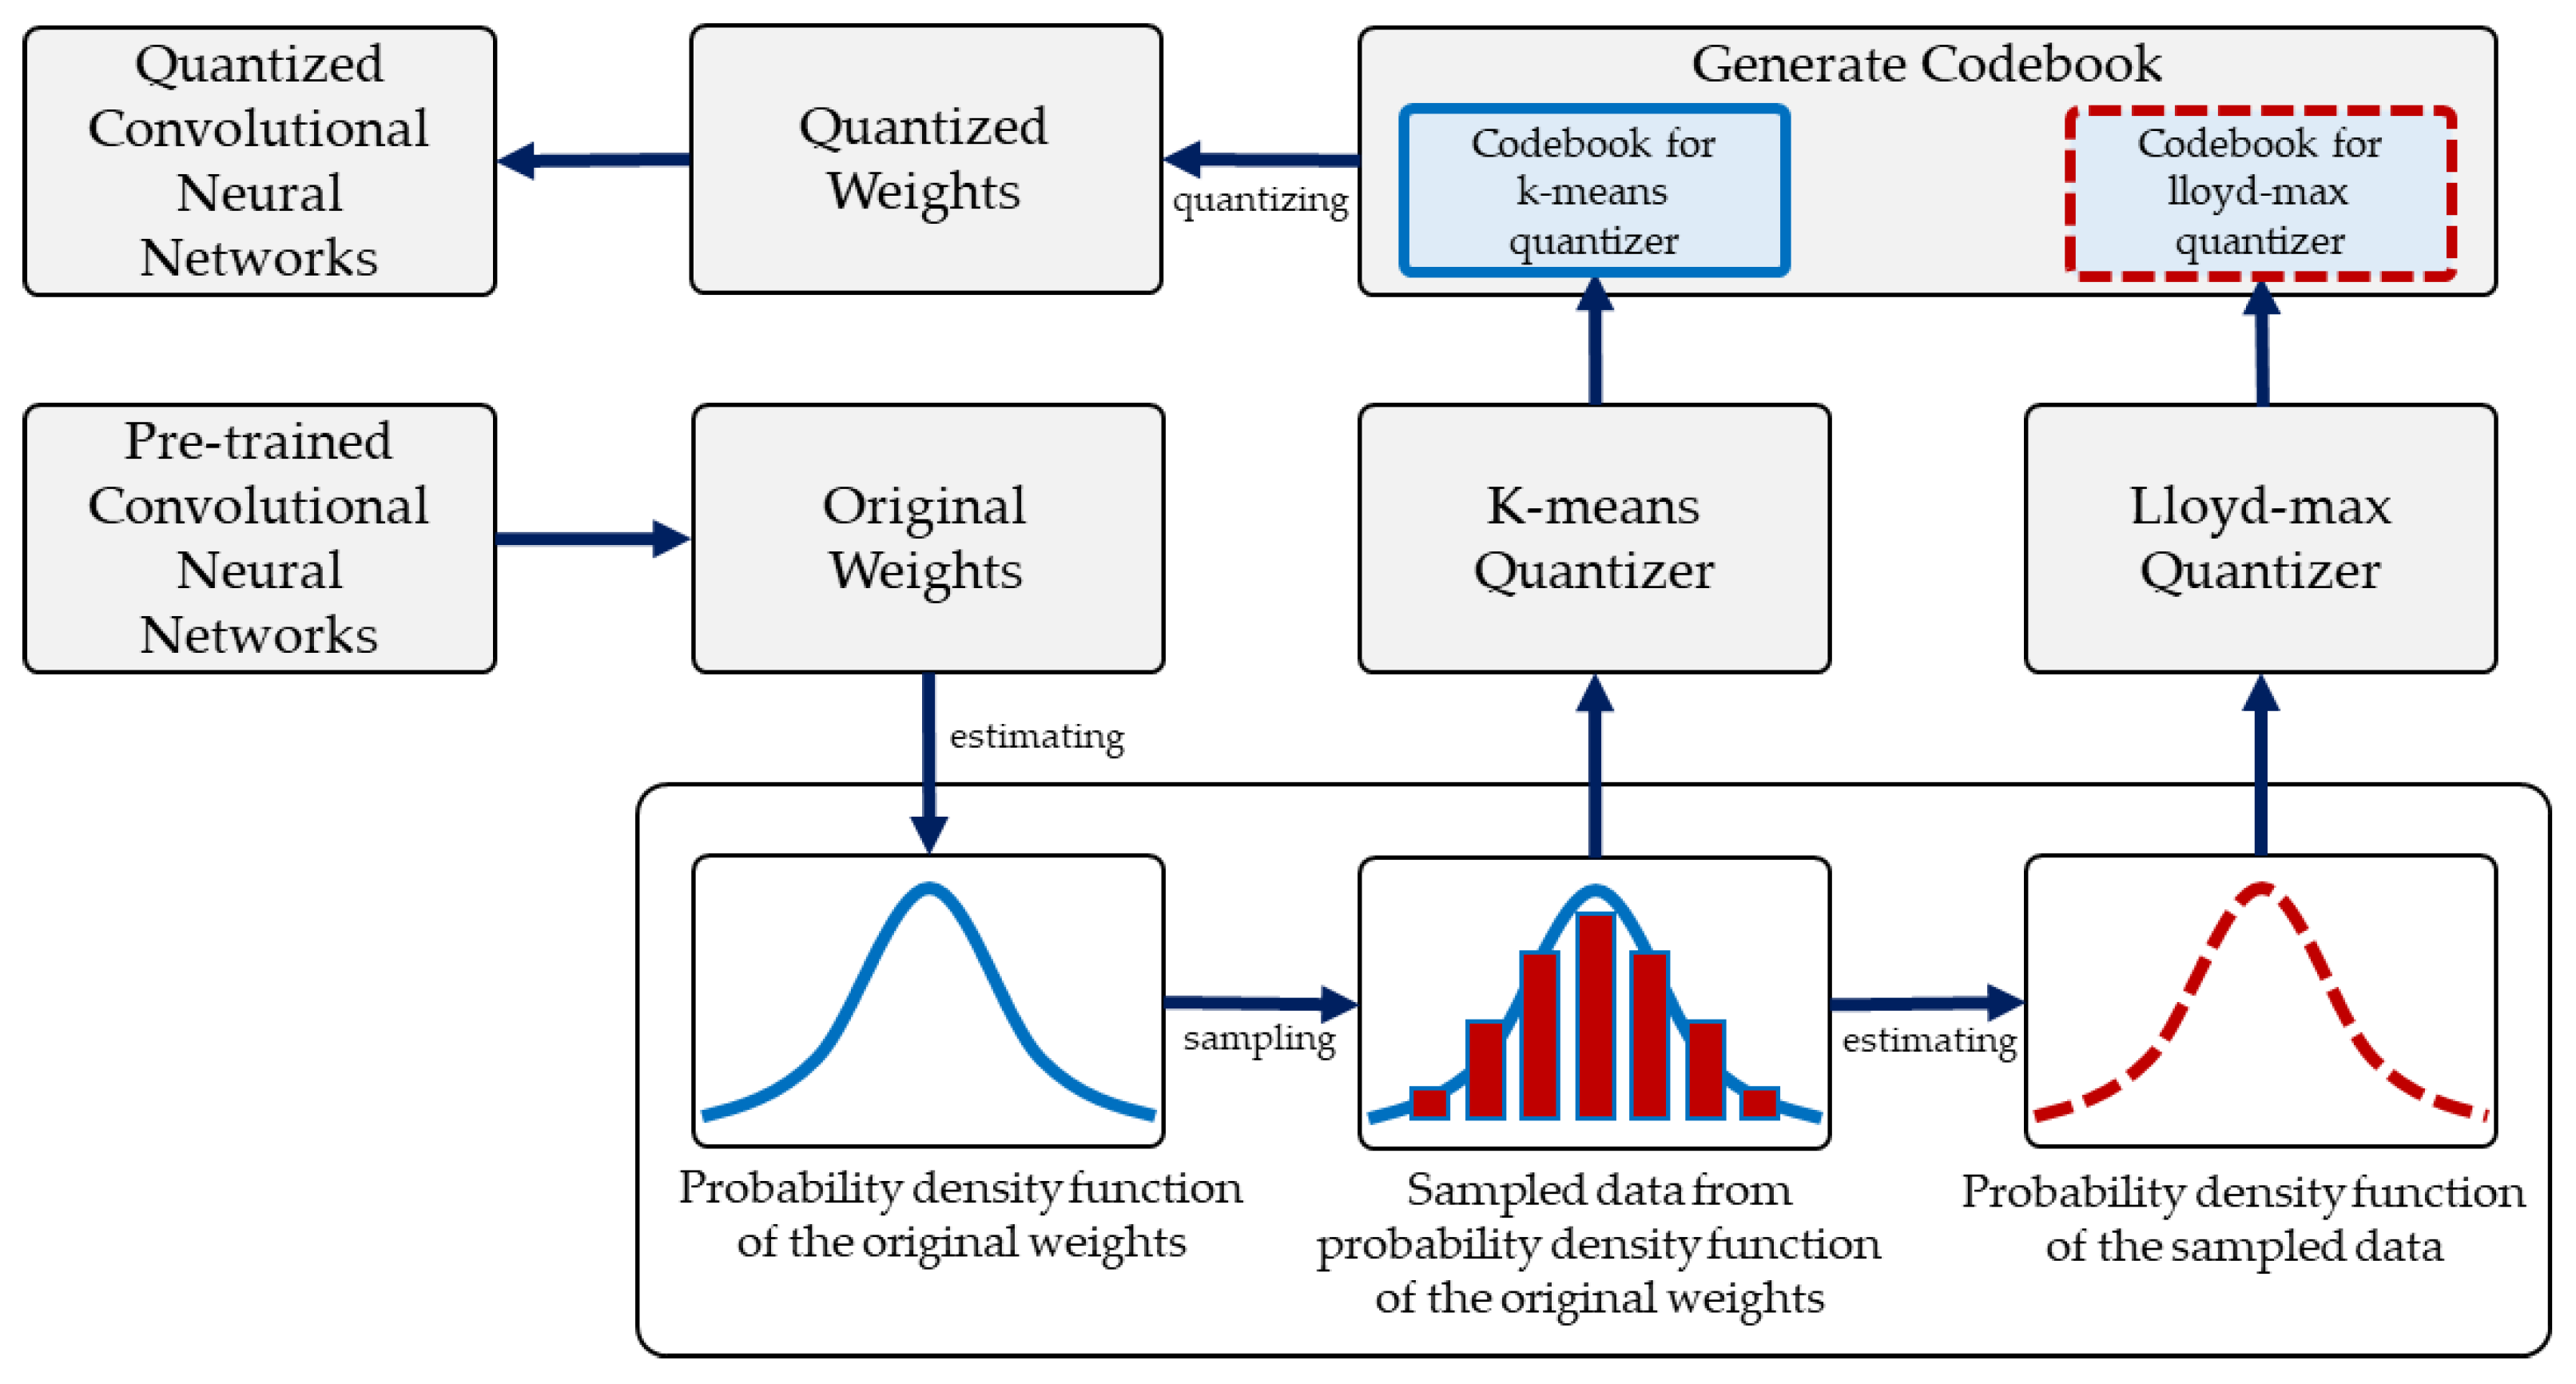
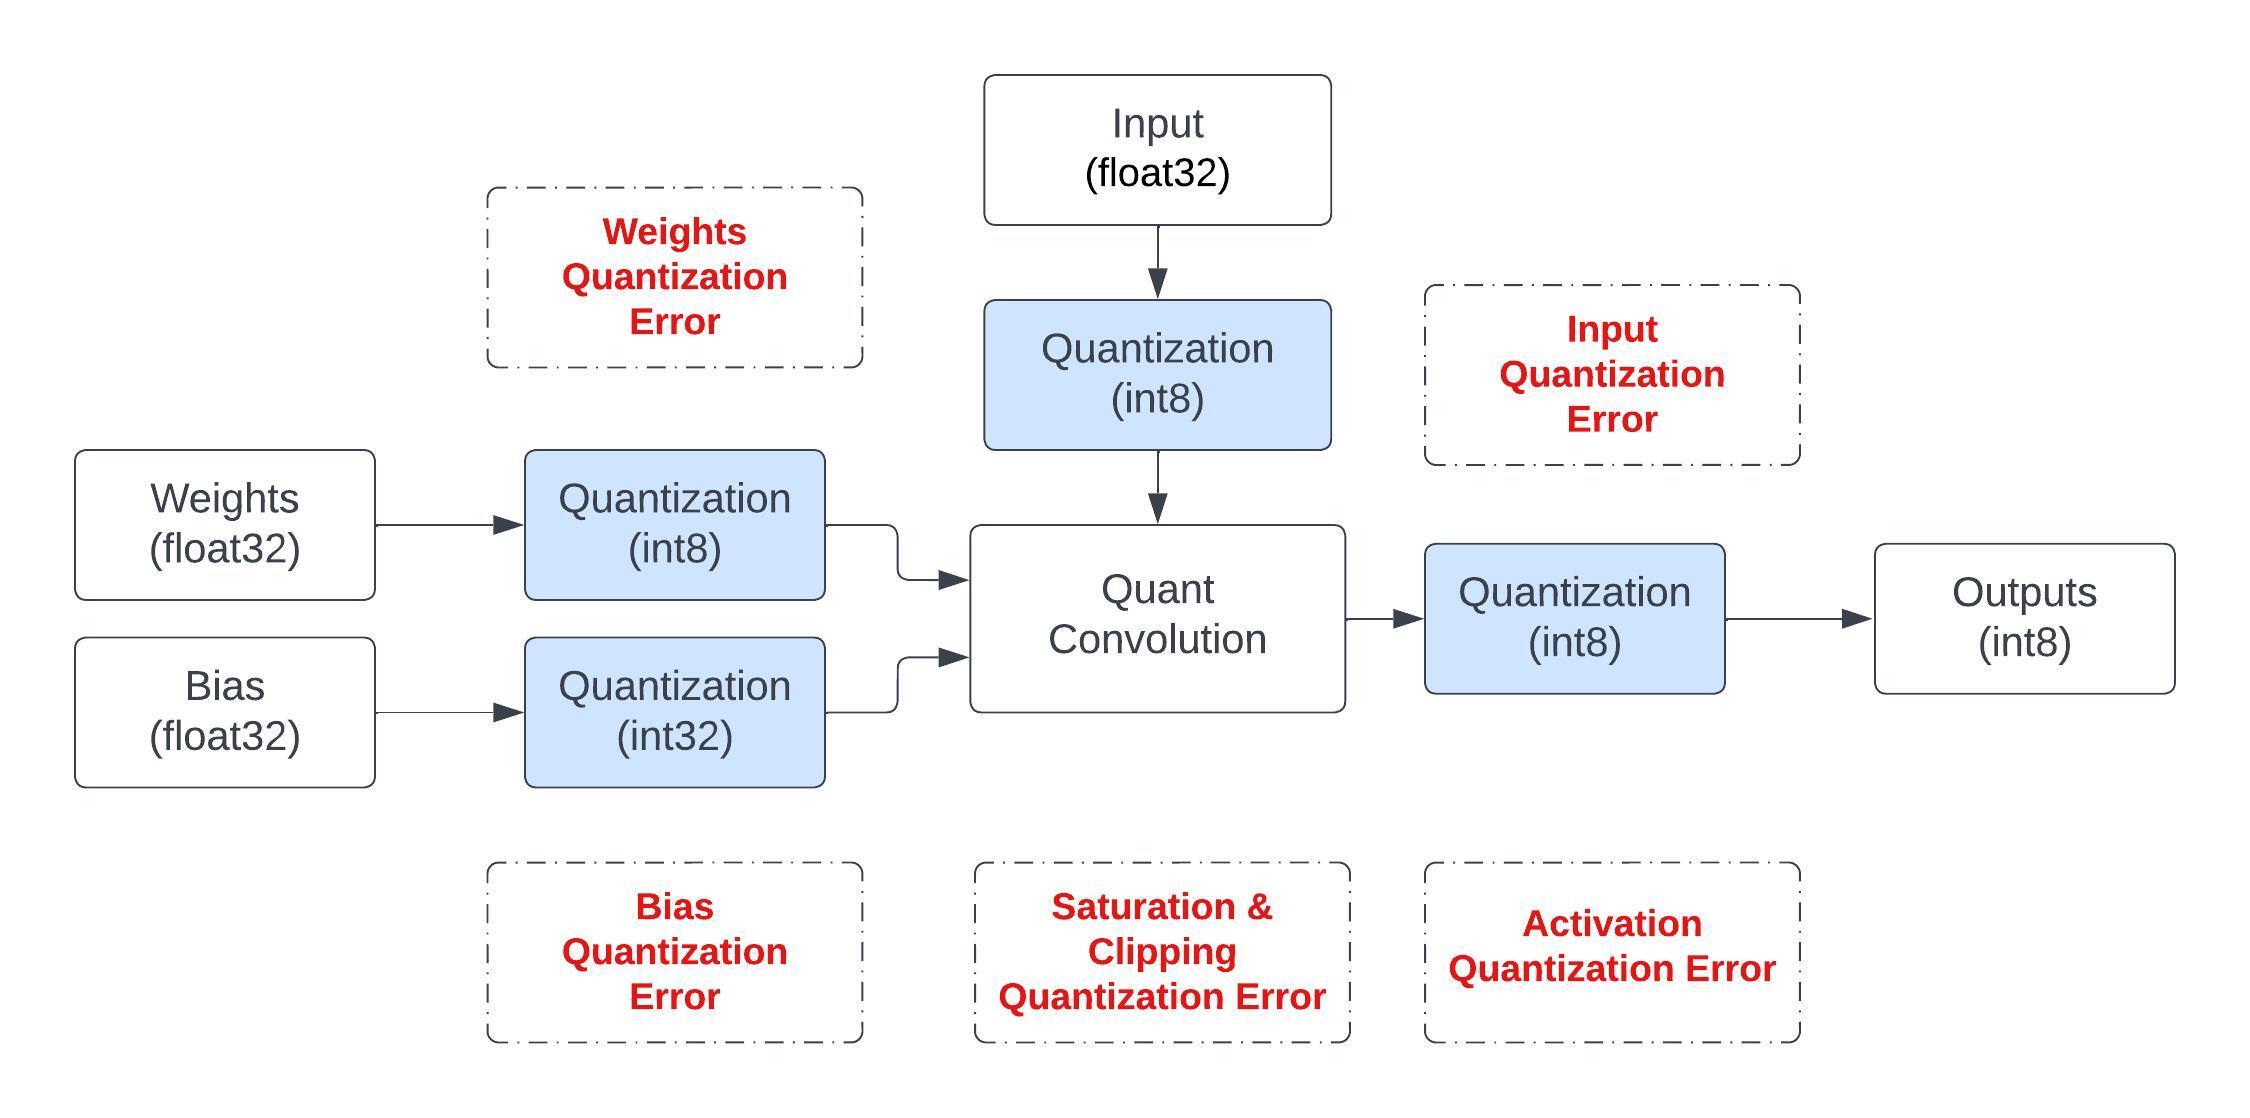
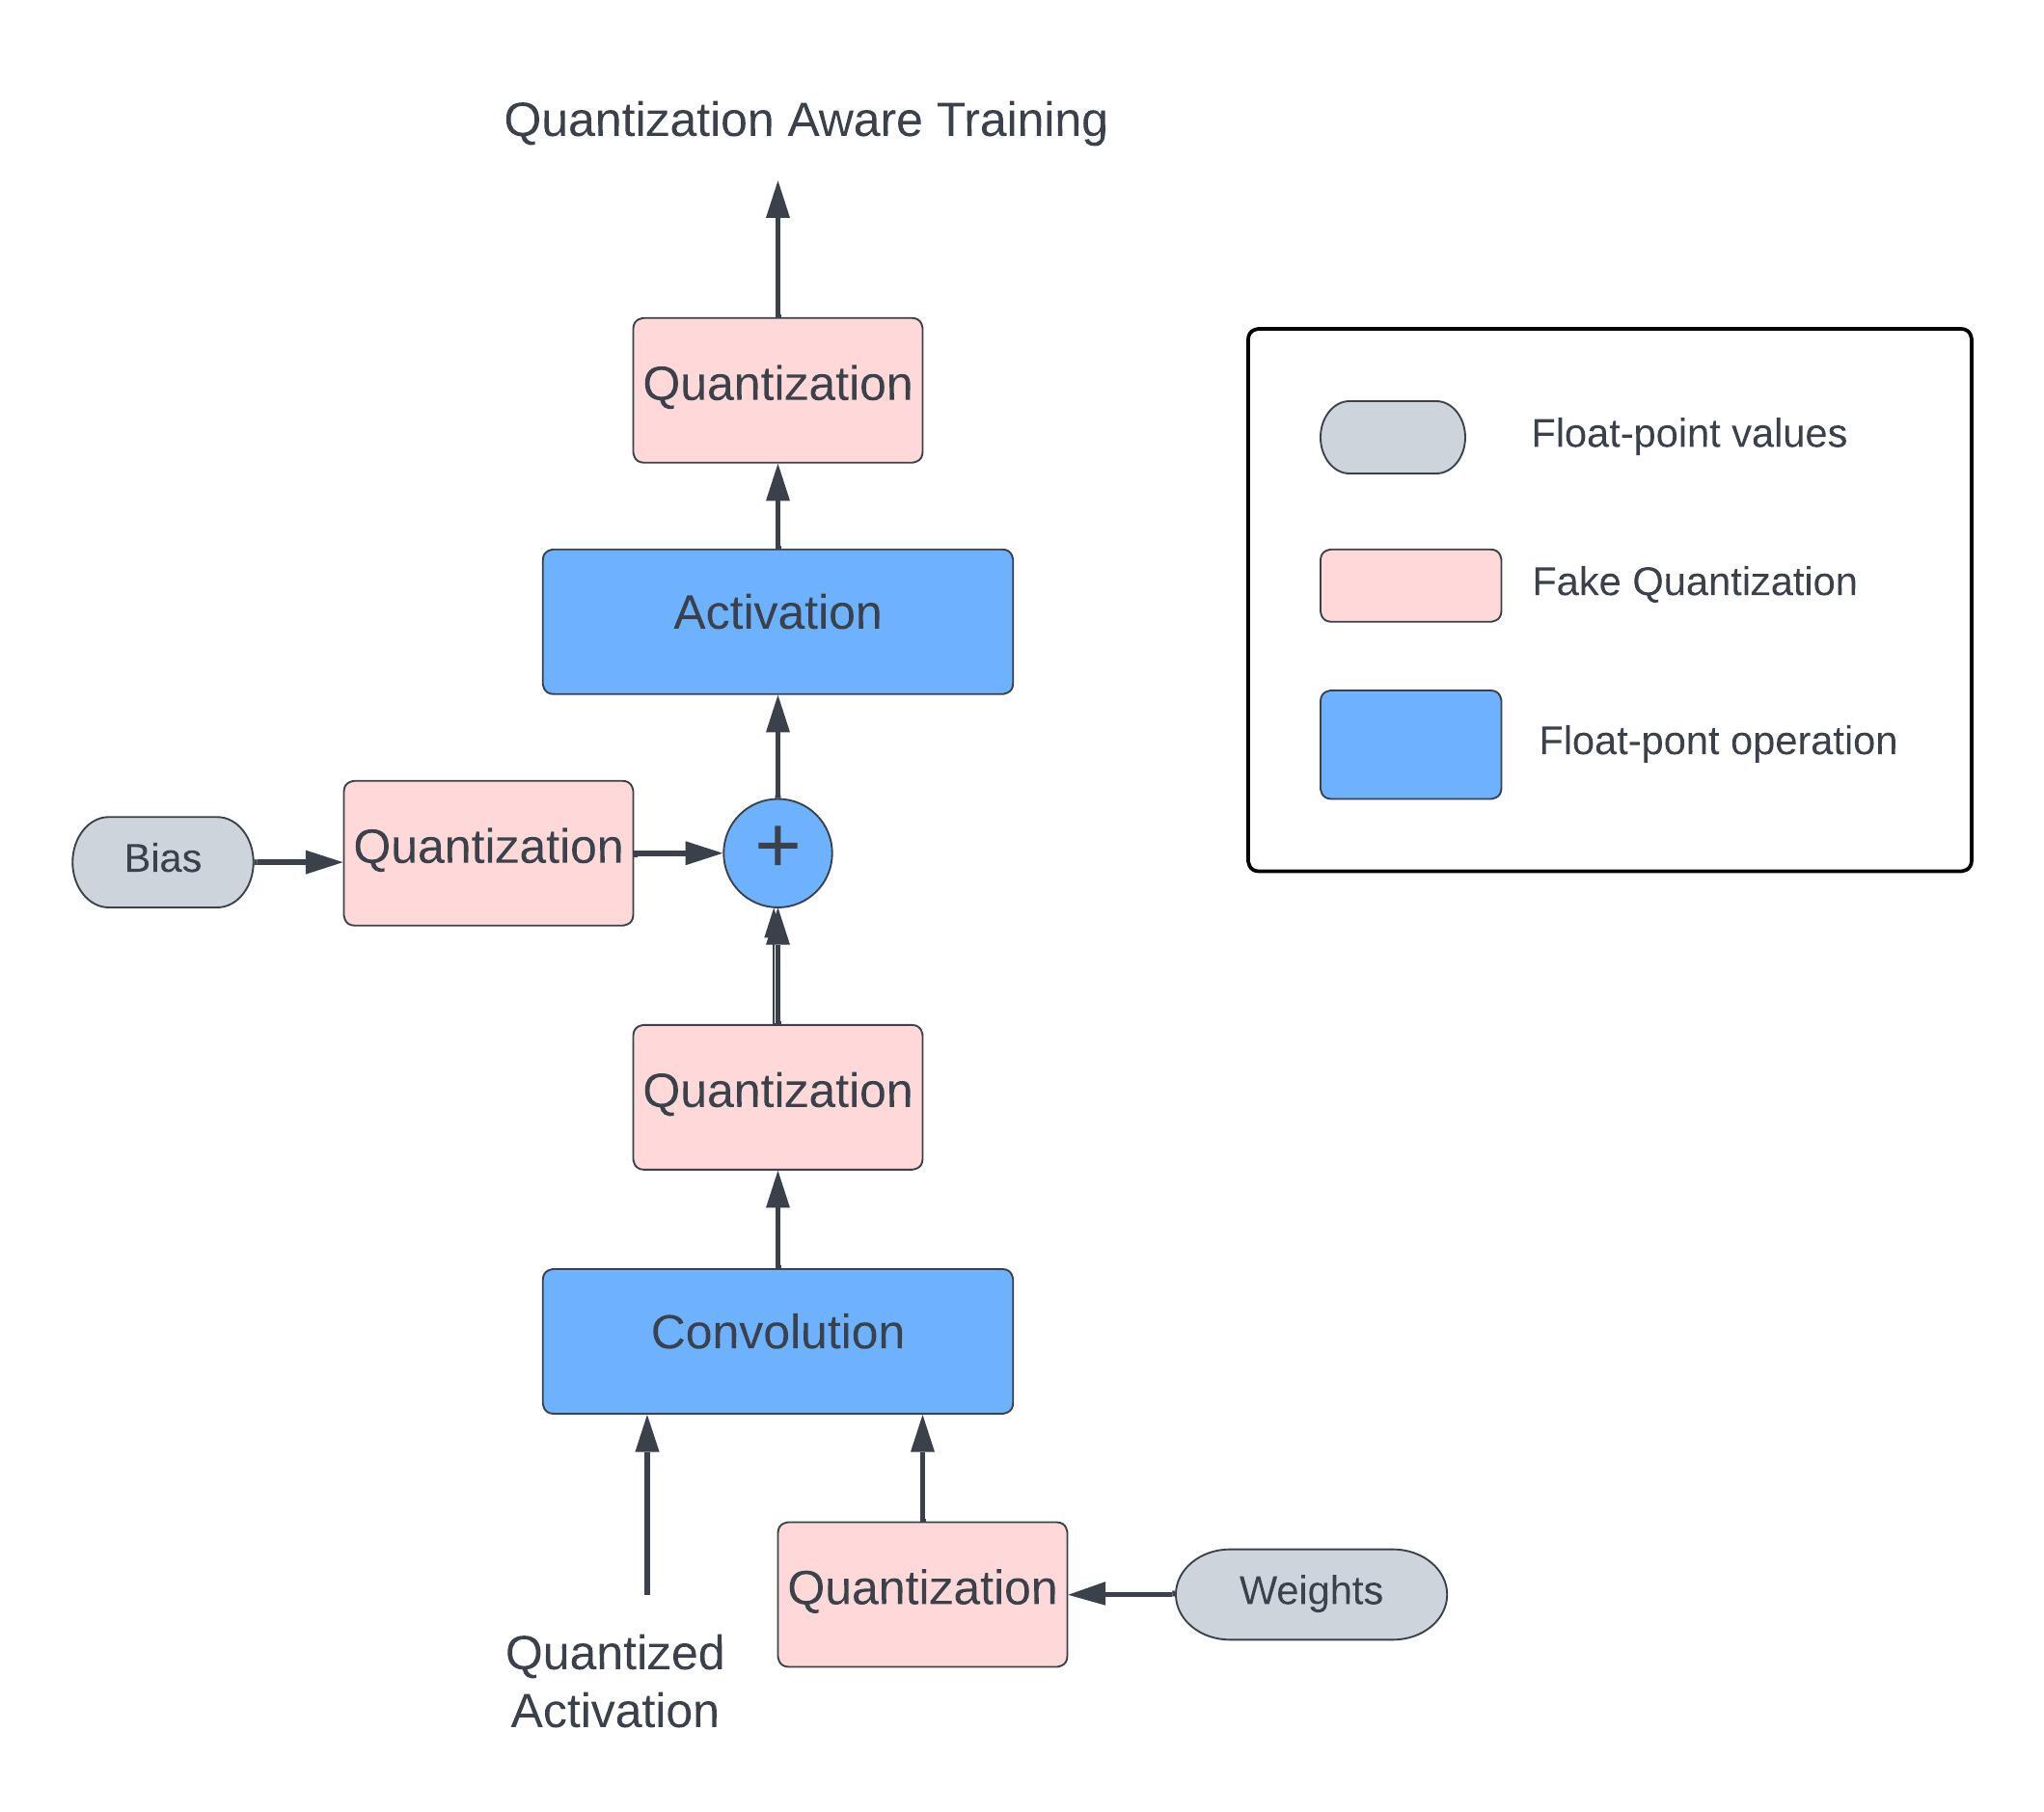
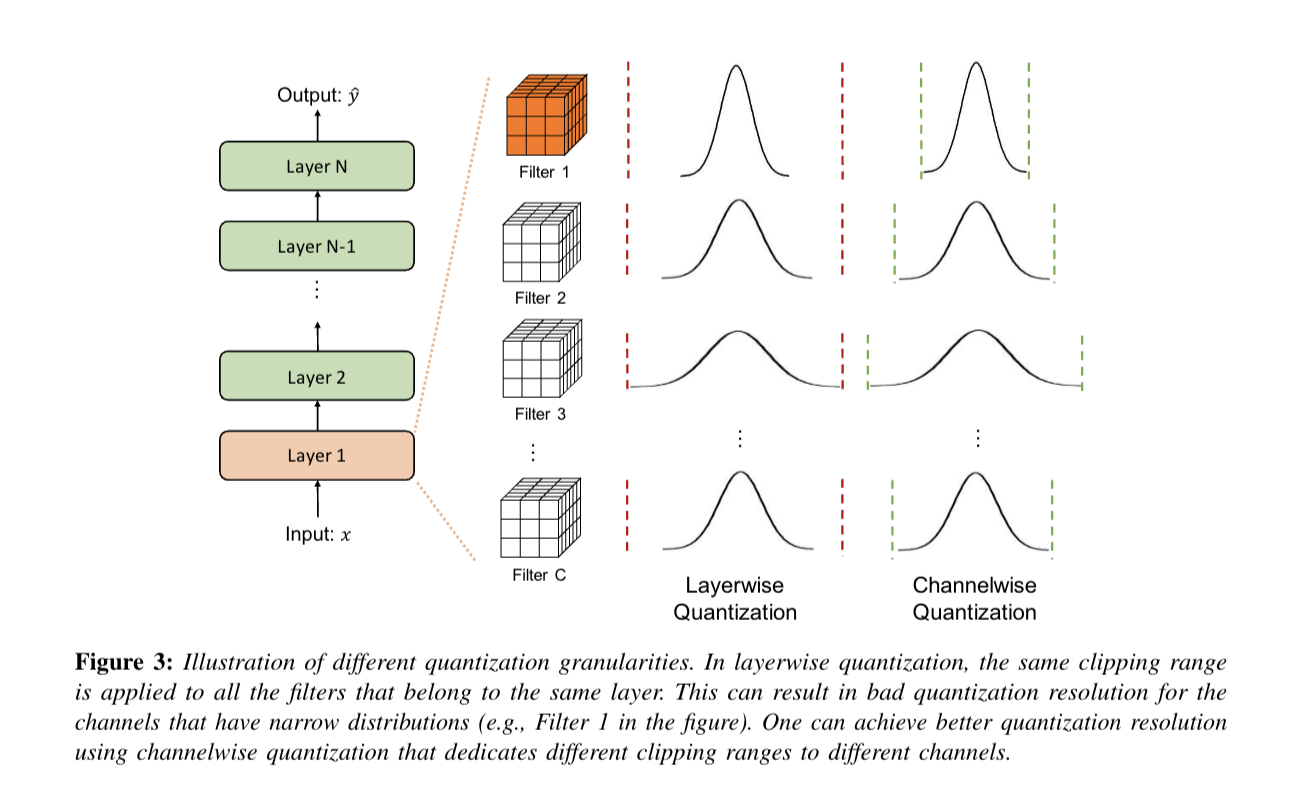
Quantization of Convolutional Neural Networks: Quantization Analysis ...
(PDF) Human Perception as a Phenomenon of Quantization
What is HumanEval ? | Deepchecks
[2103.13630] A Survey of Quantization Methods for Efficient Neural ...
Quantization of Convolutional Neural Networks: Model Quantization ...
HumanEval - AI Benchmark Explained | DemandSphere
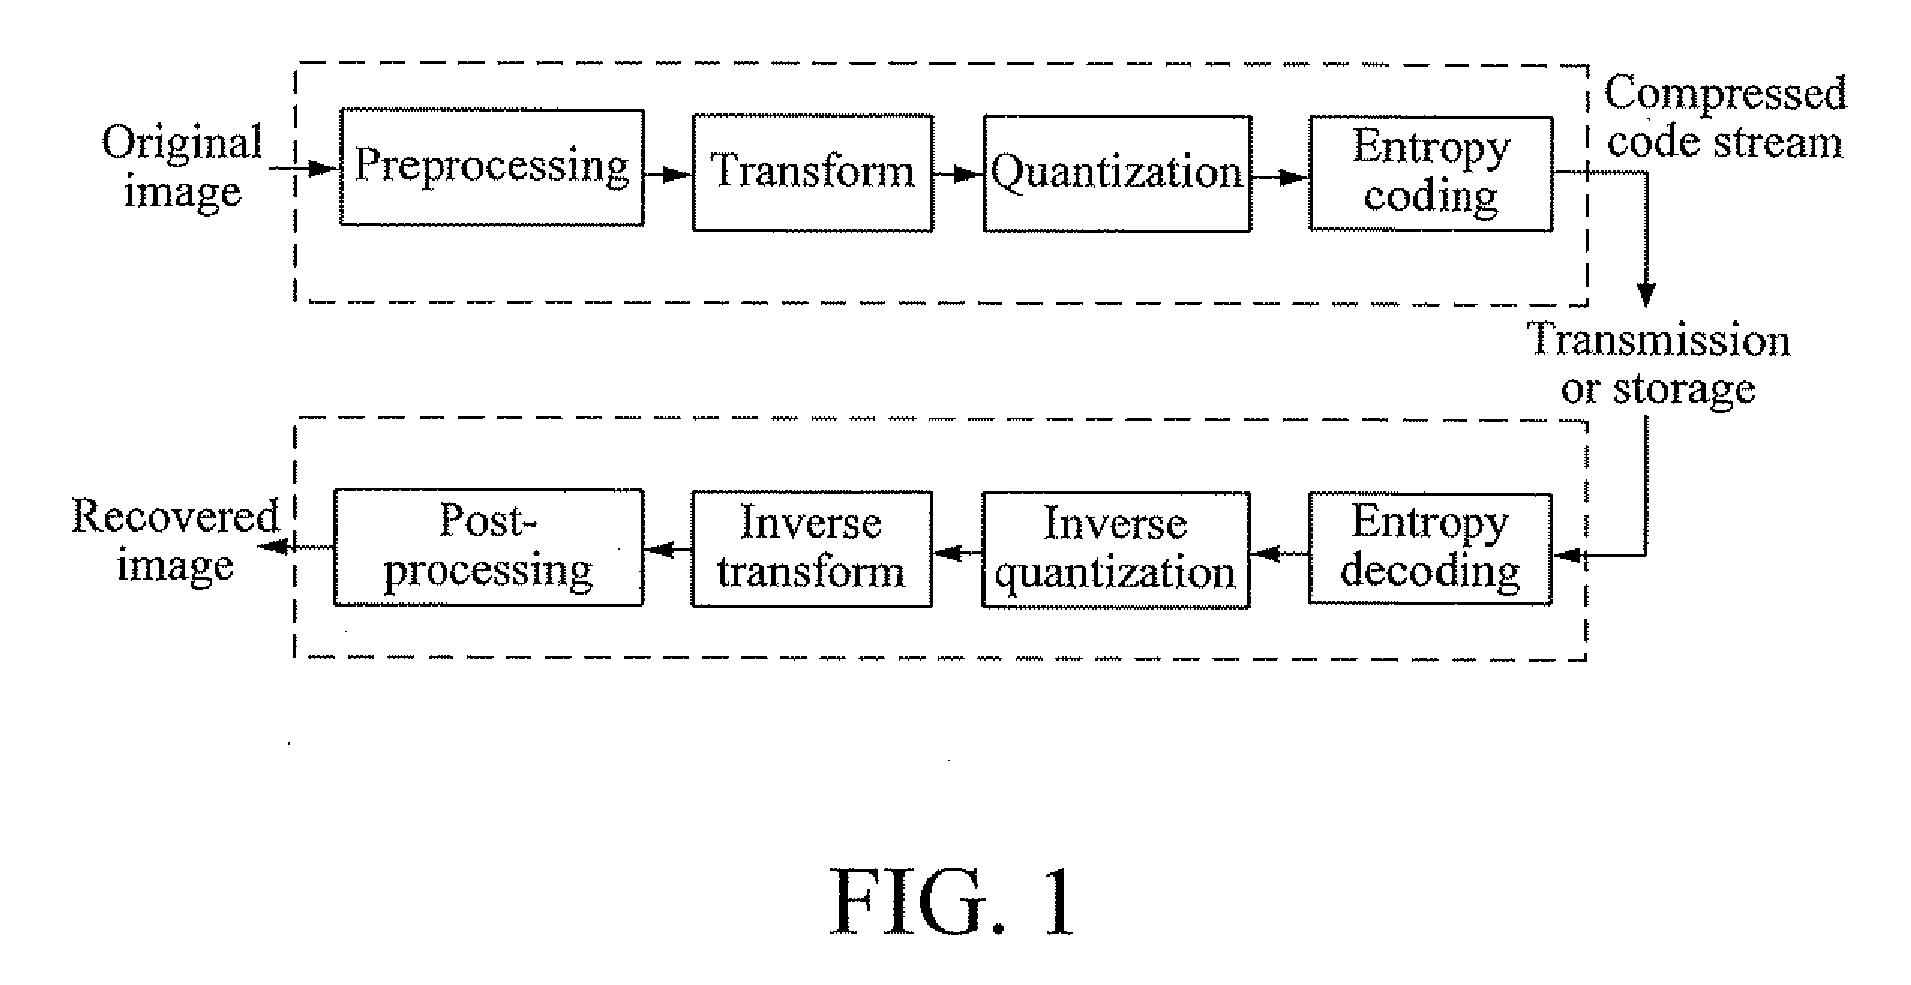
Wavelet coefficient quantization method using human visual model in ...
Quantization in the context of deep learning and neural networks
Andy - 在 CodeLLM 的 evaluation 當中,我們最常看到的就是 HumanEval 這組 Benchmark。這篇文章 ...
Figure 1 from Human Visual Perception-Based Quantization For Efficiency ...
Figure 1 from Designing Quantization Table for Hadamard Transform based ...
A Deep Dive into Model Quantization for Large-Scale Deployment ...
Quantization - Rafay Product Documentation
A Survey of Quantization Methods for Efficient Neural Network Inference
What is Quantization - GeeksforGeeks
A Survey of Quantization Methods for Efficient Neural Network Inference ...
Optimize and deploy LLMs for production with OpenShift AI | Red Hat ...
CodeGeeX vs. its quantized version on code generation of HumanEval-X ...
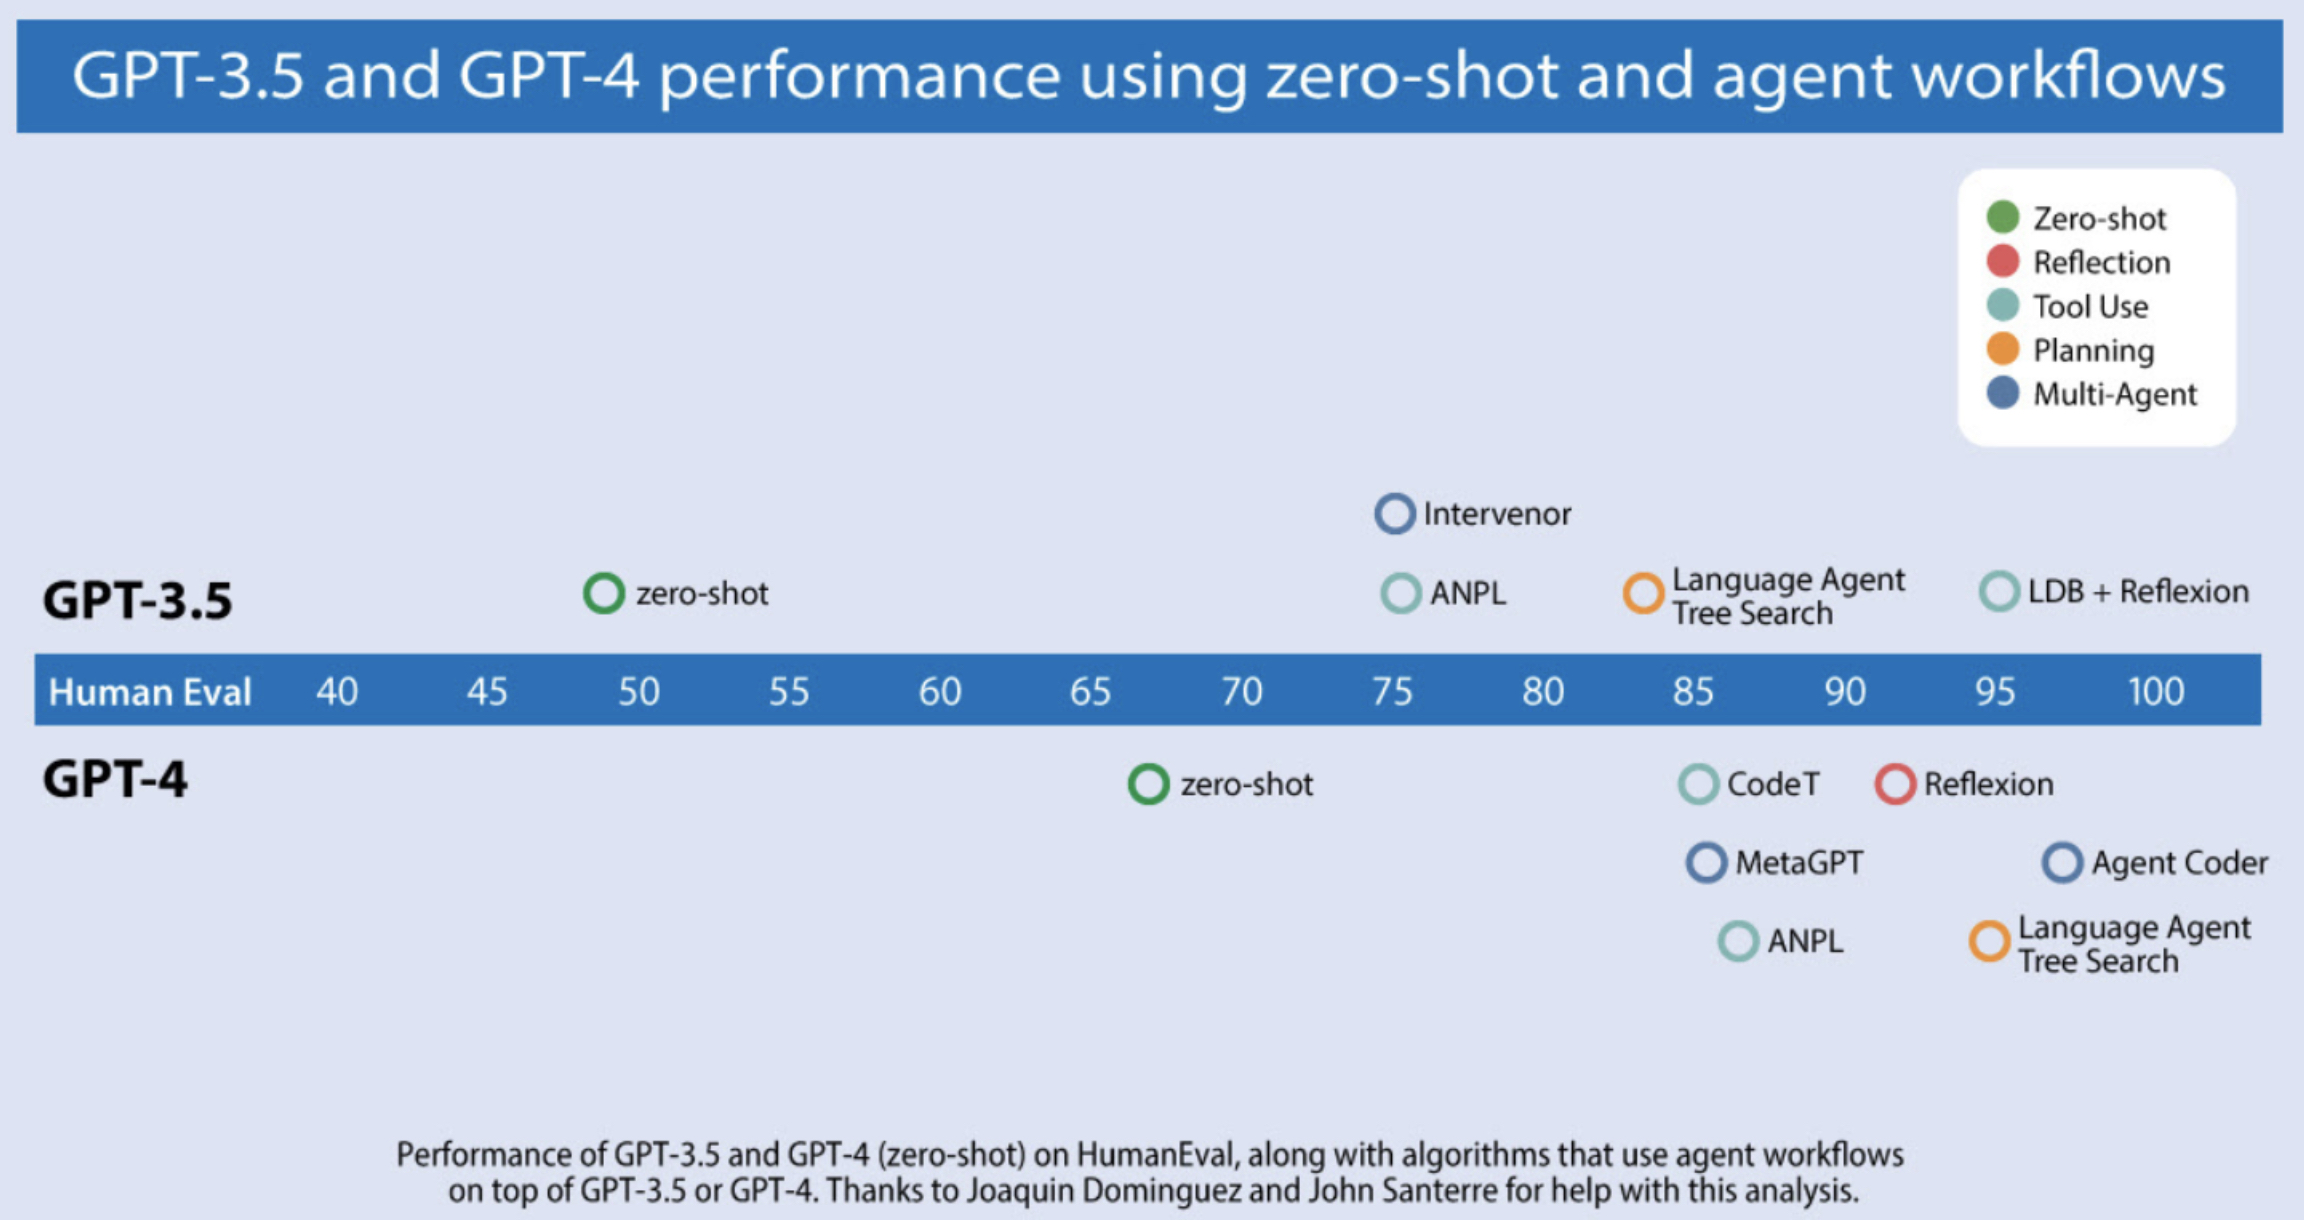
LLM Agents - Miguel's Blog
How to Interpret HumanEval: Can this AI Actually Code?
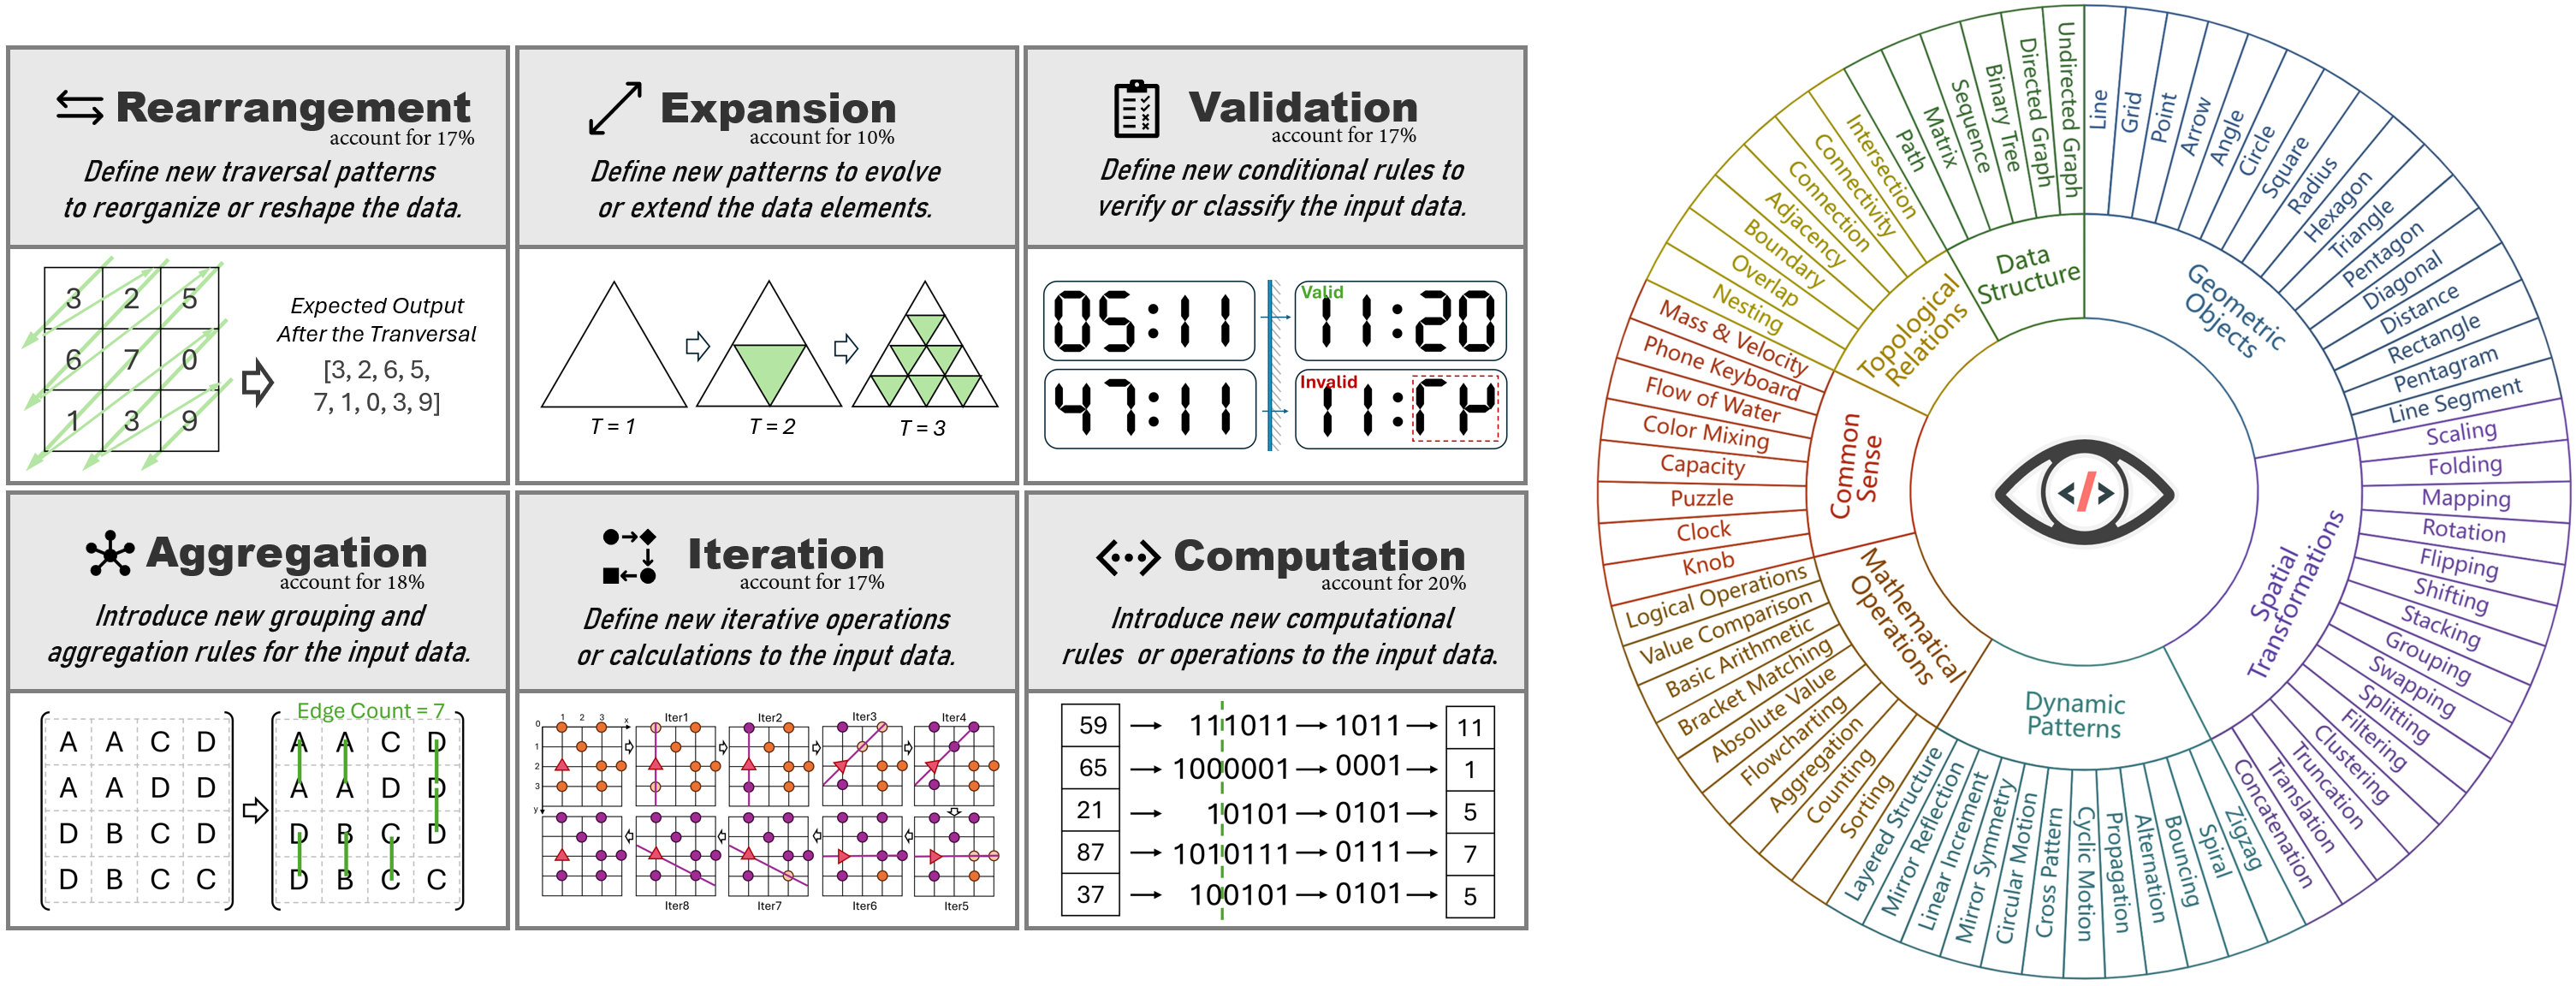
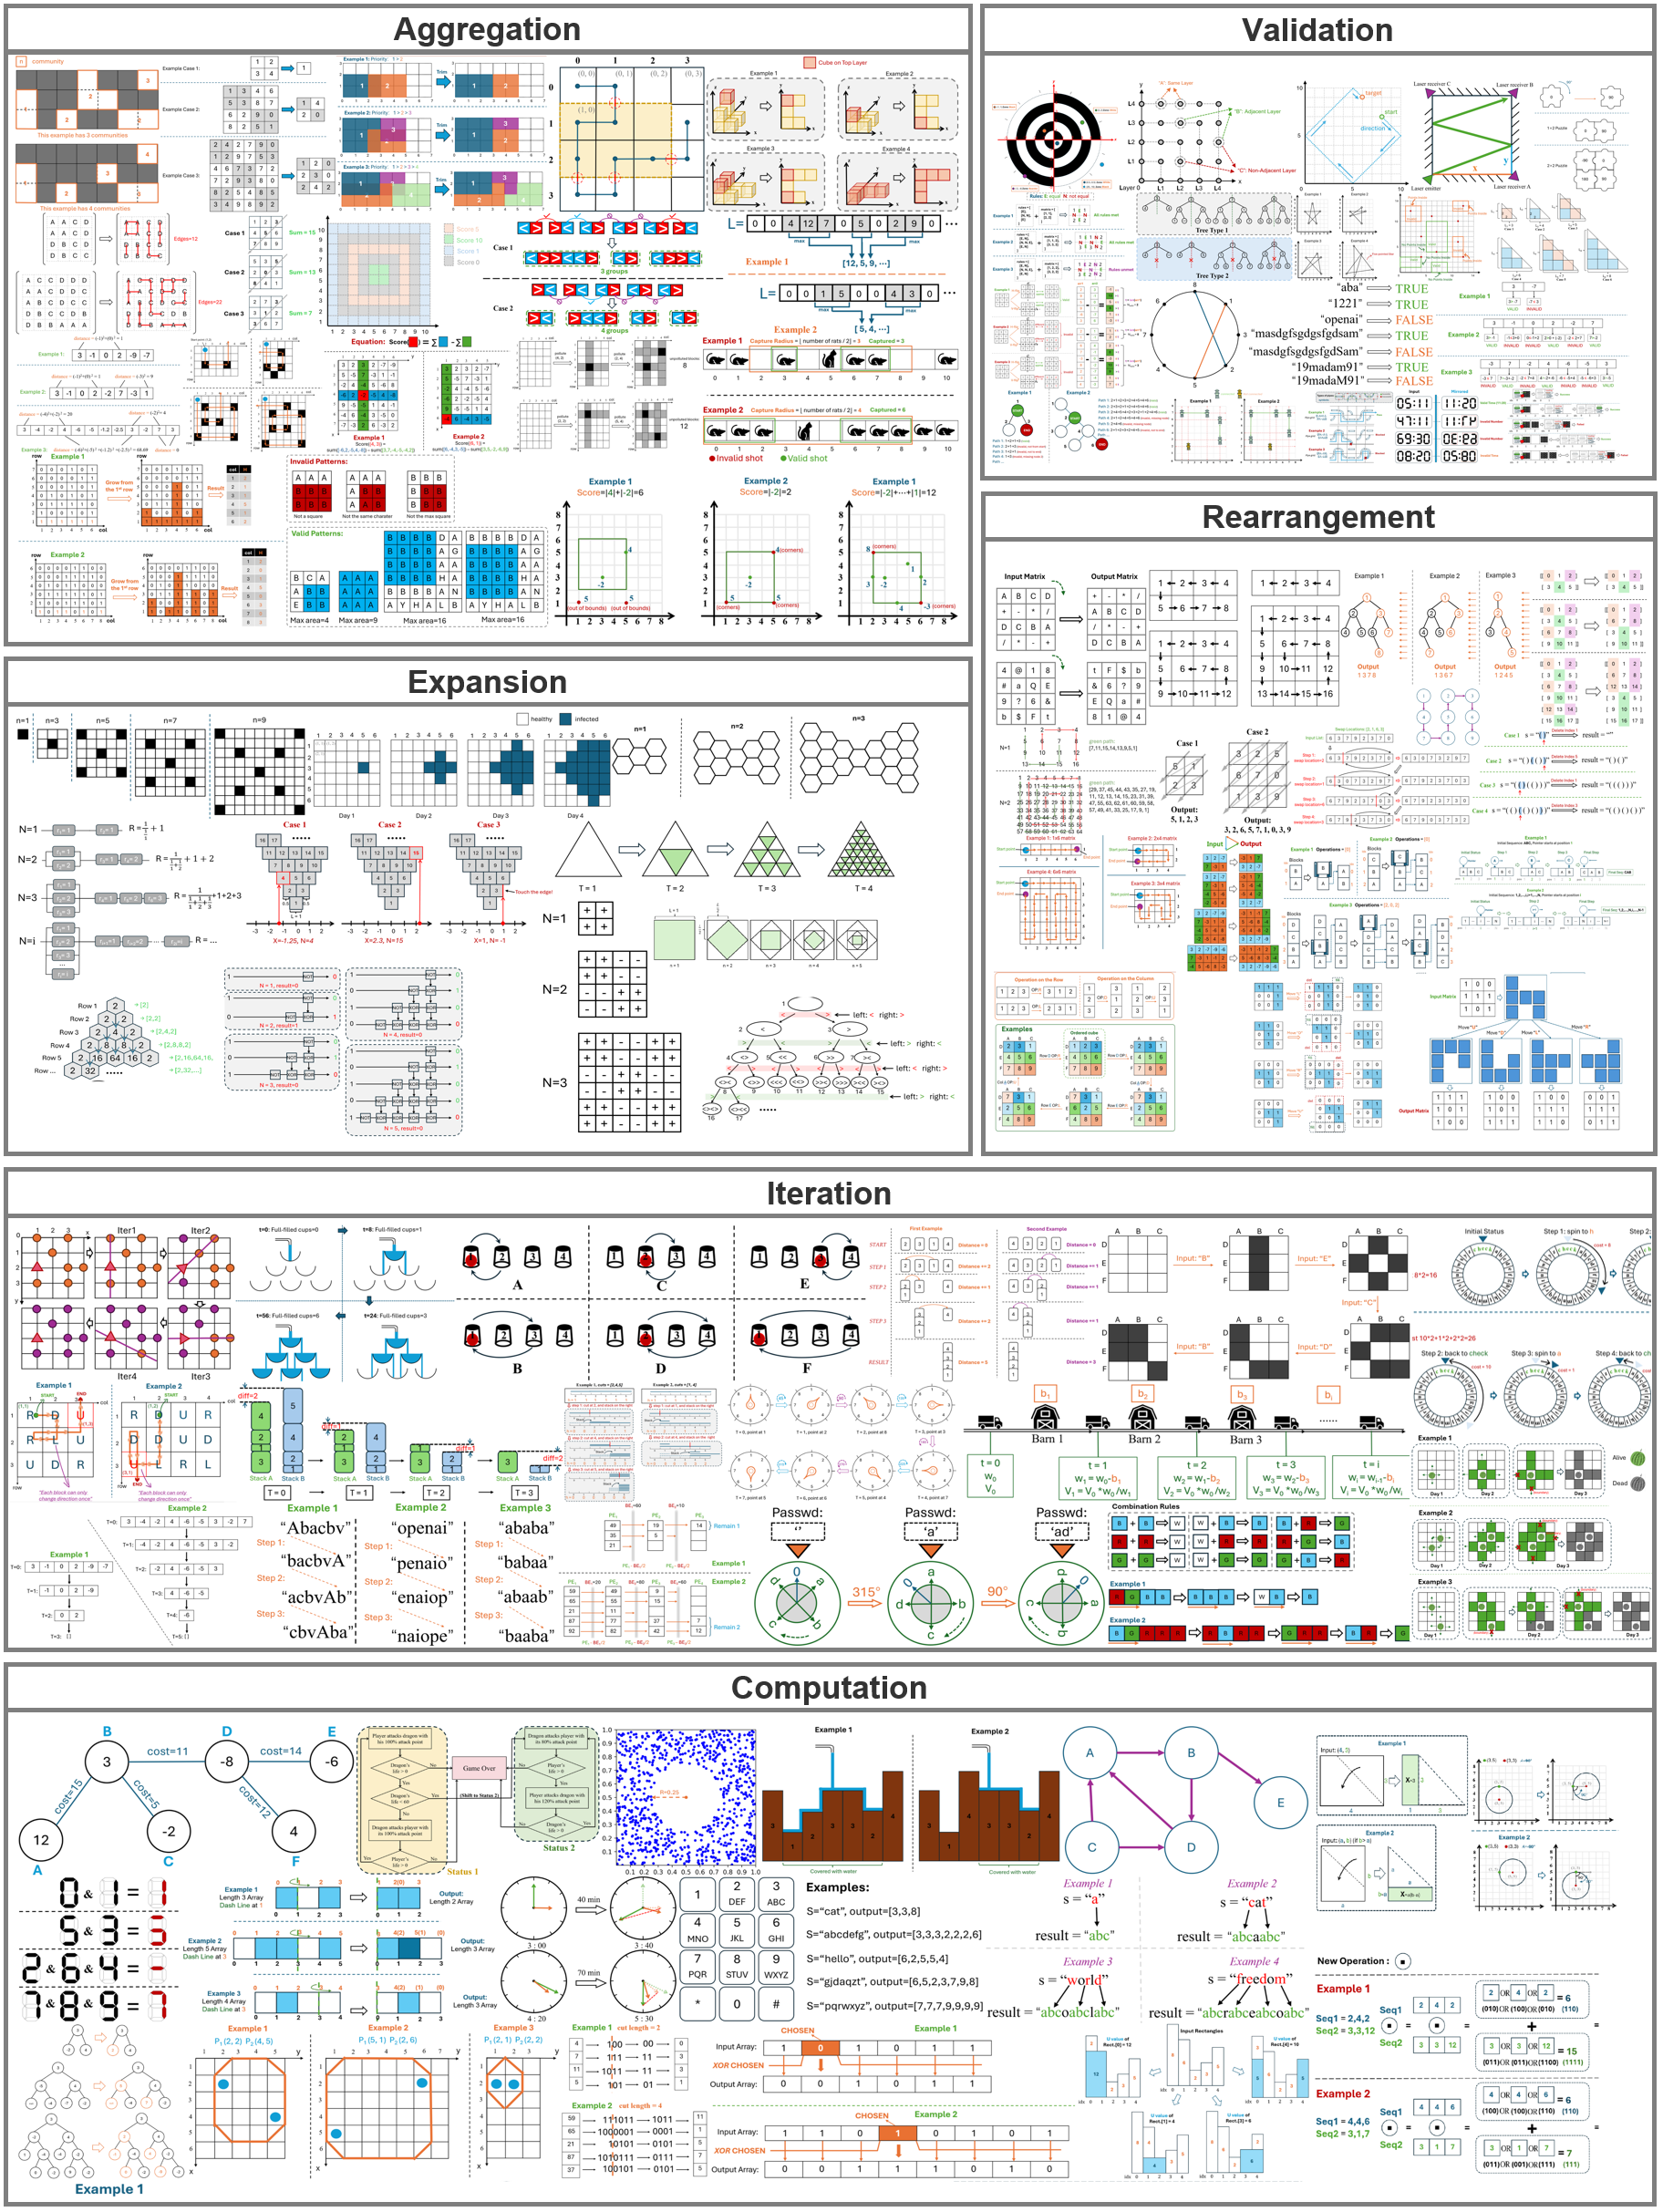
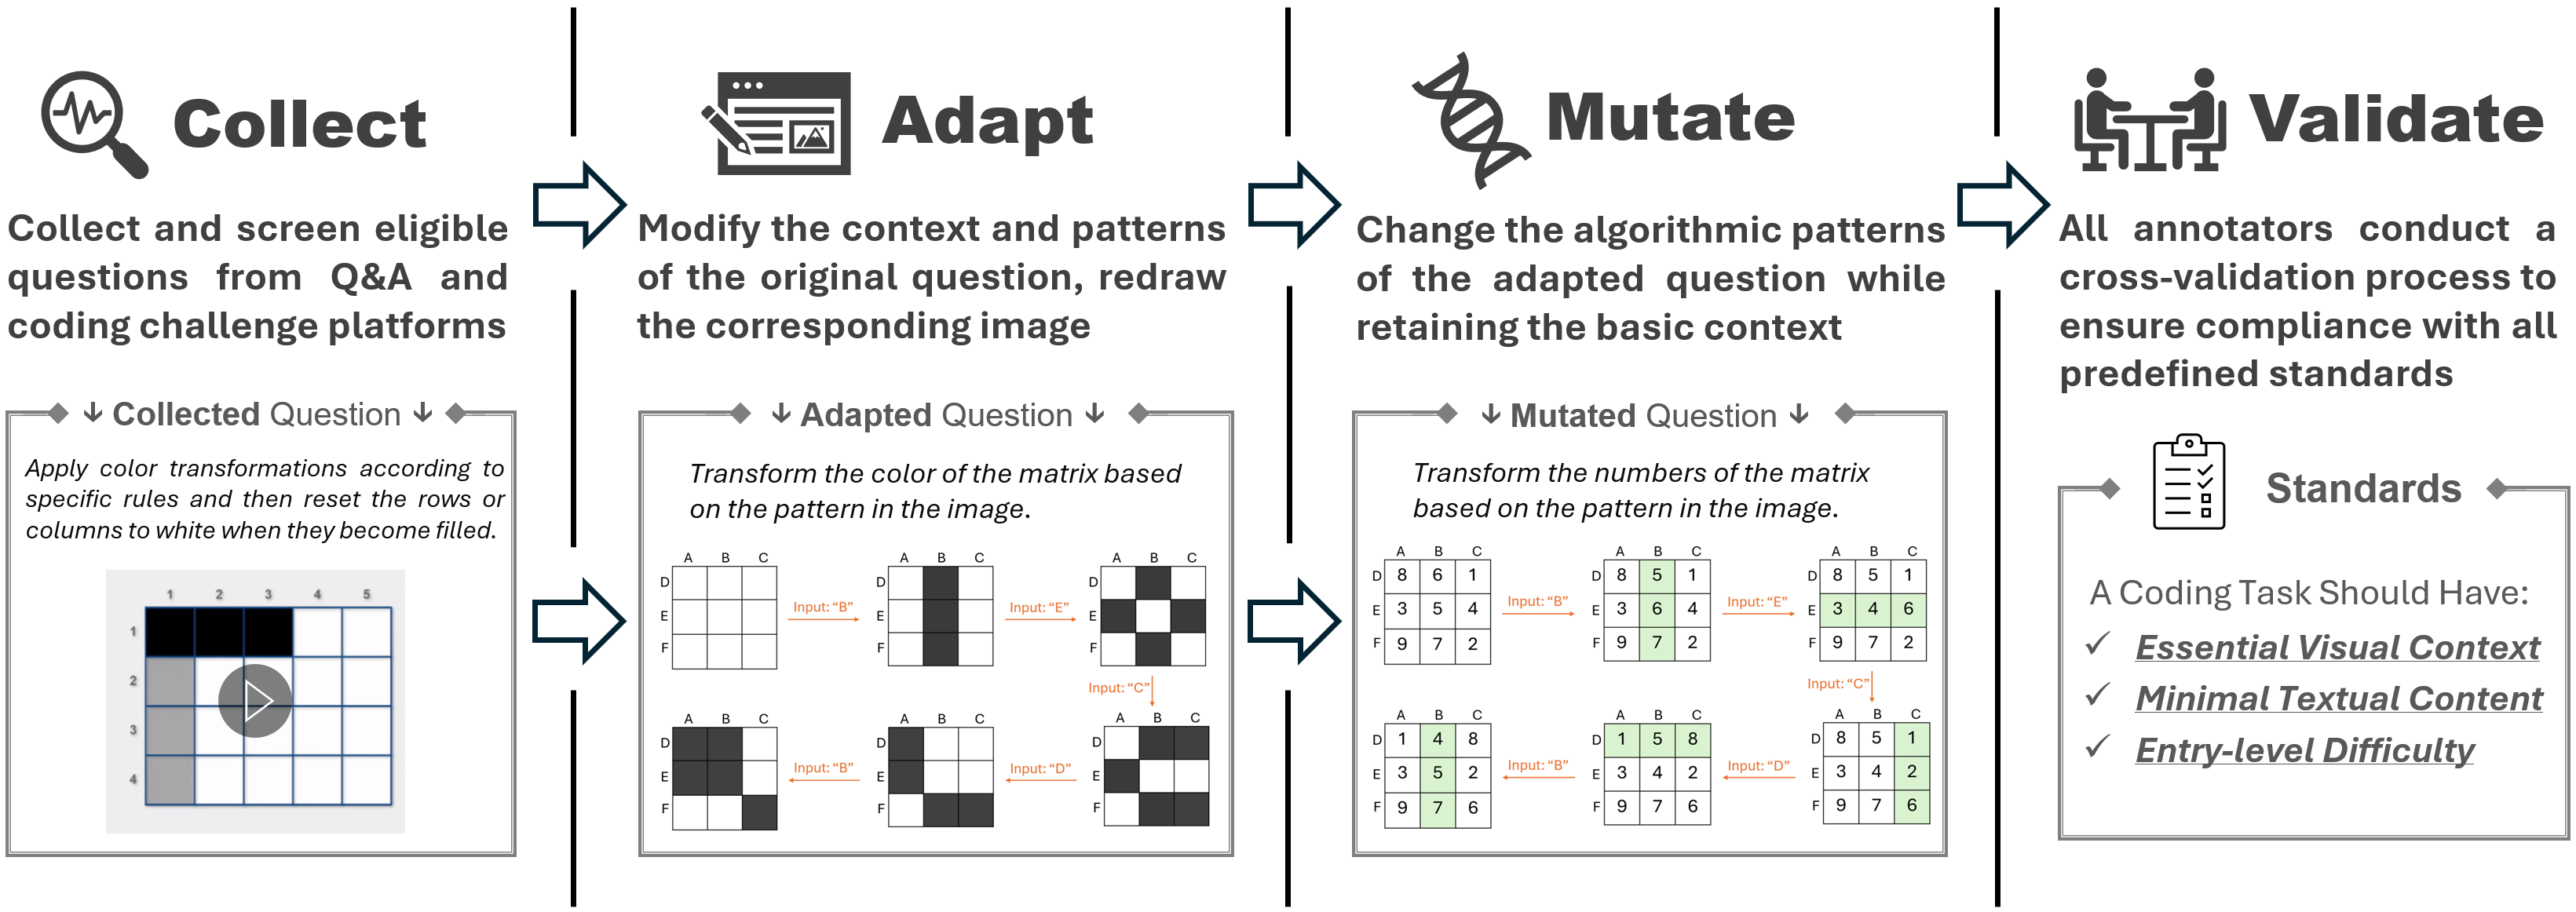
HumanEval-V
LLM评测一:HumanEval+ - 知乎
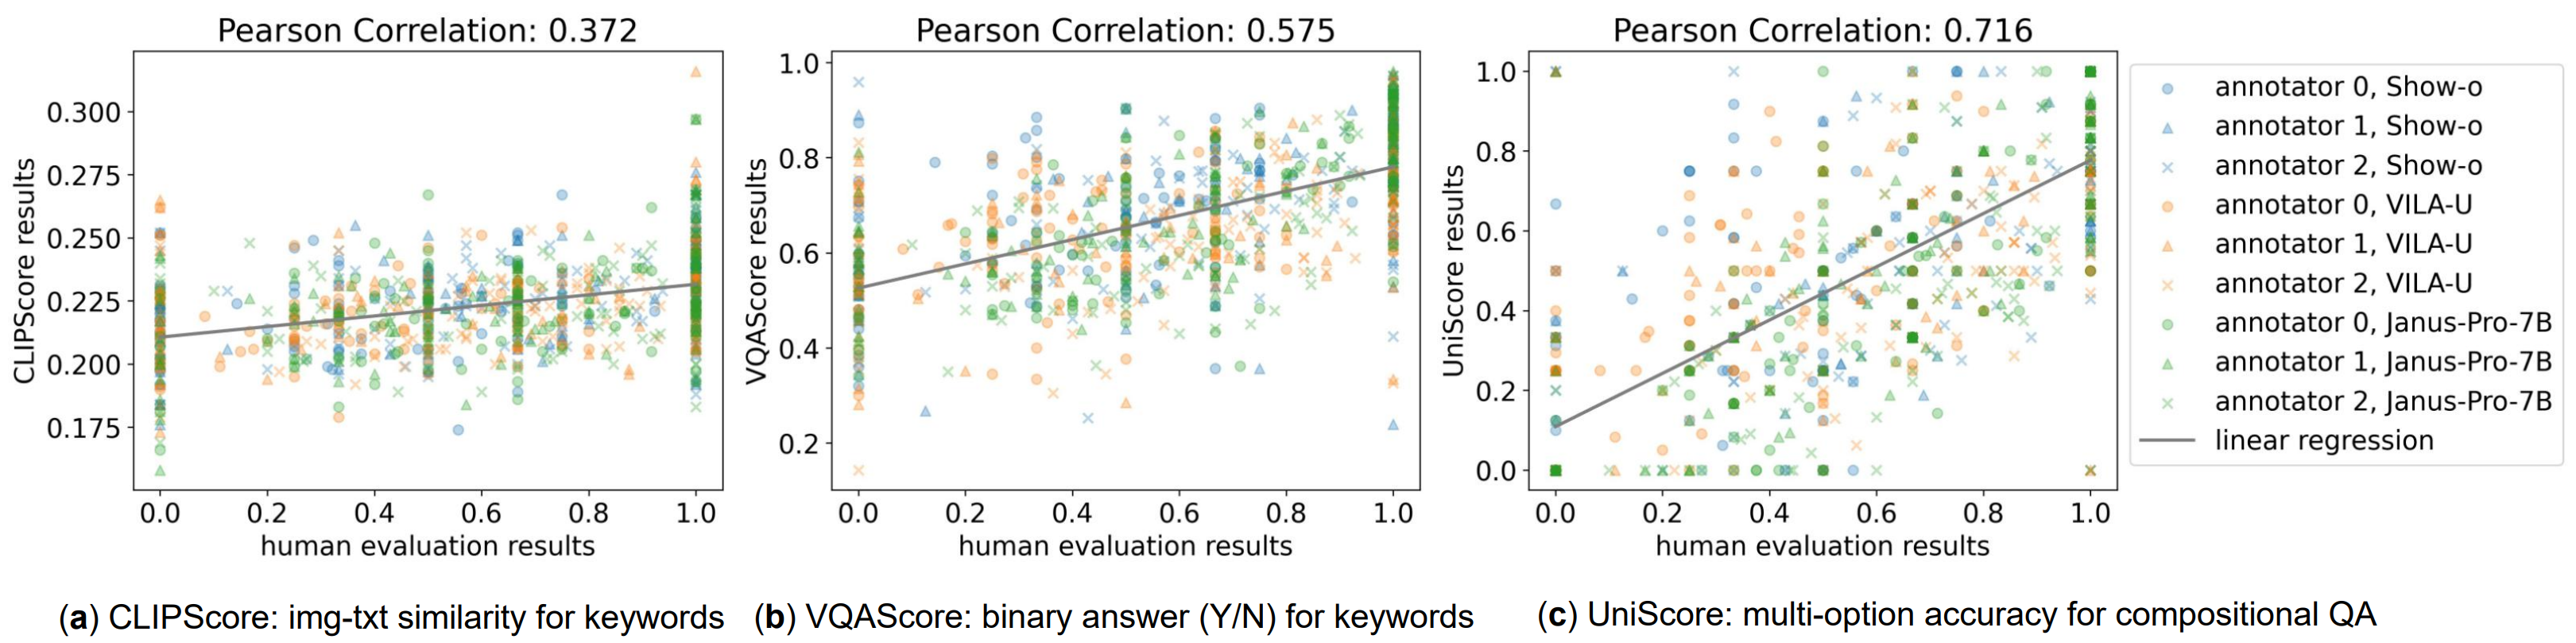
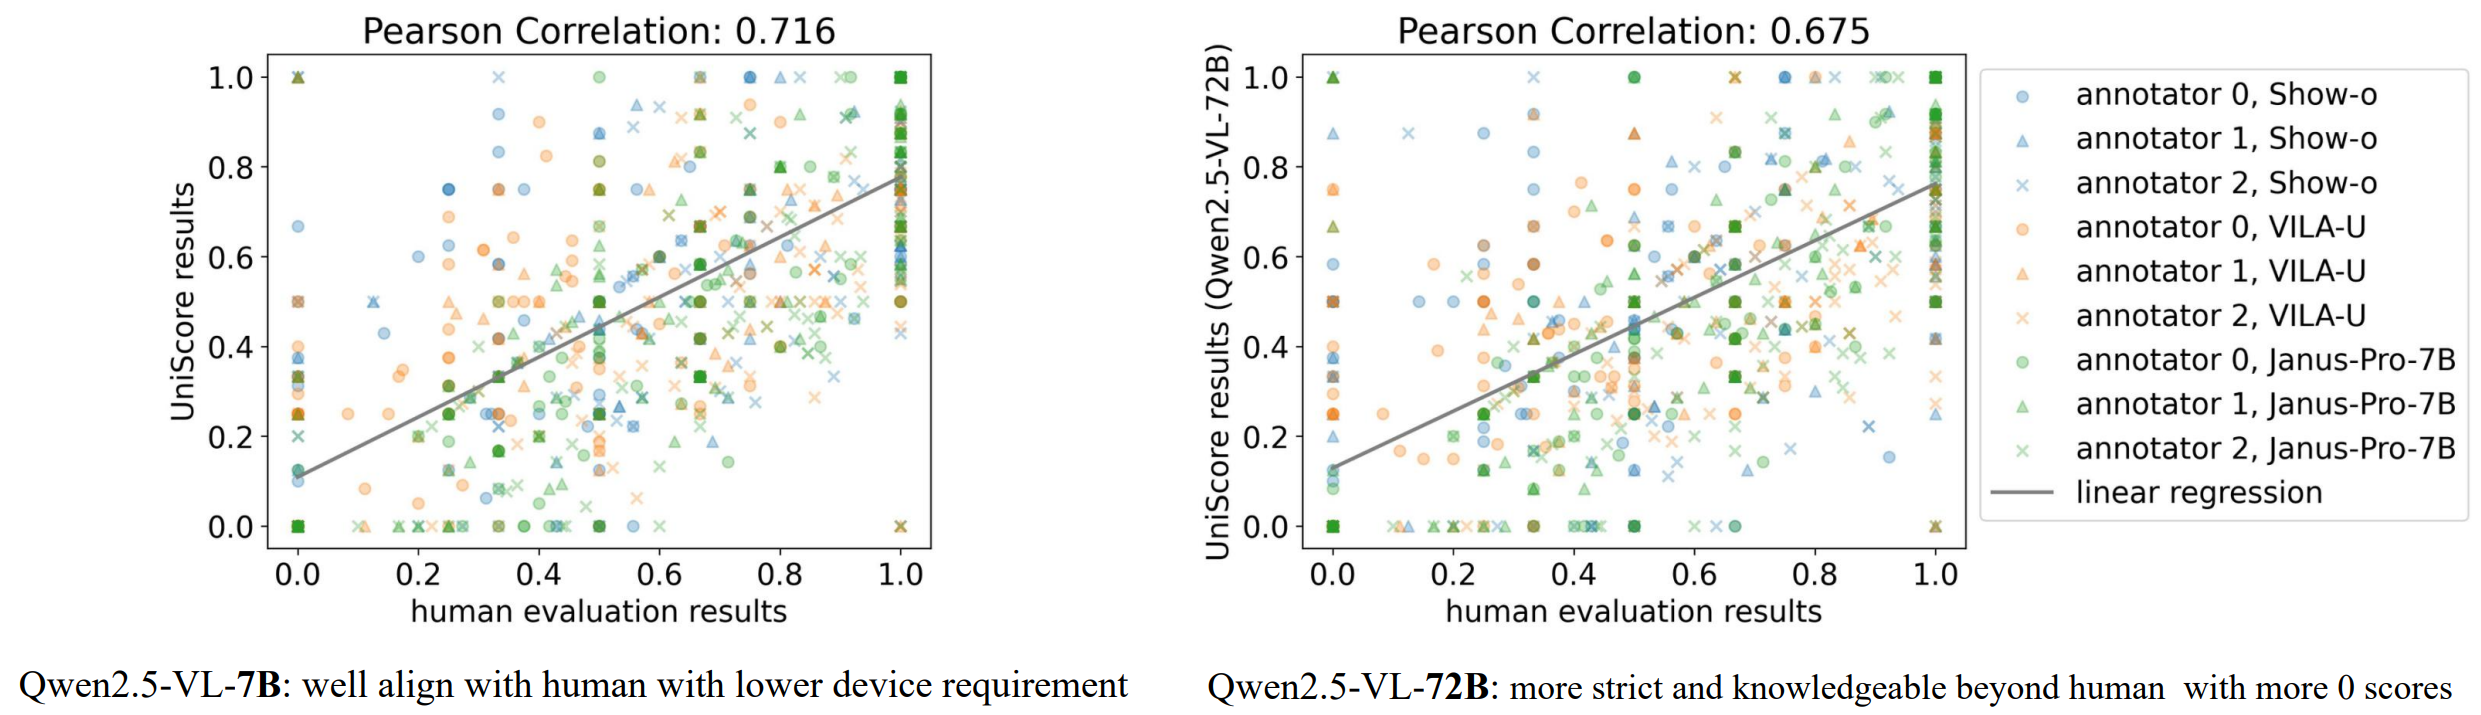
UniEval | UniEval: Unified Holistic Evaluation for Unified Multimodal ...
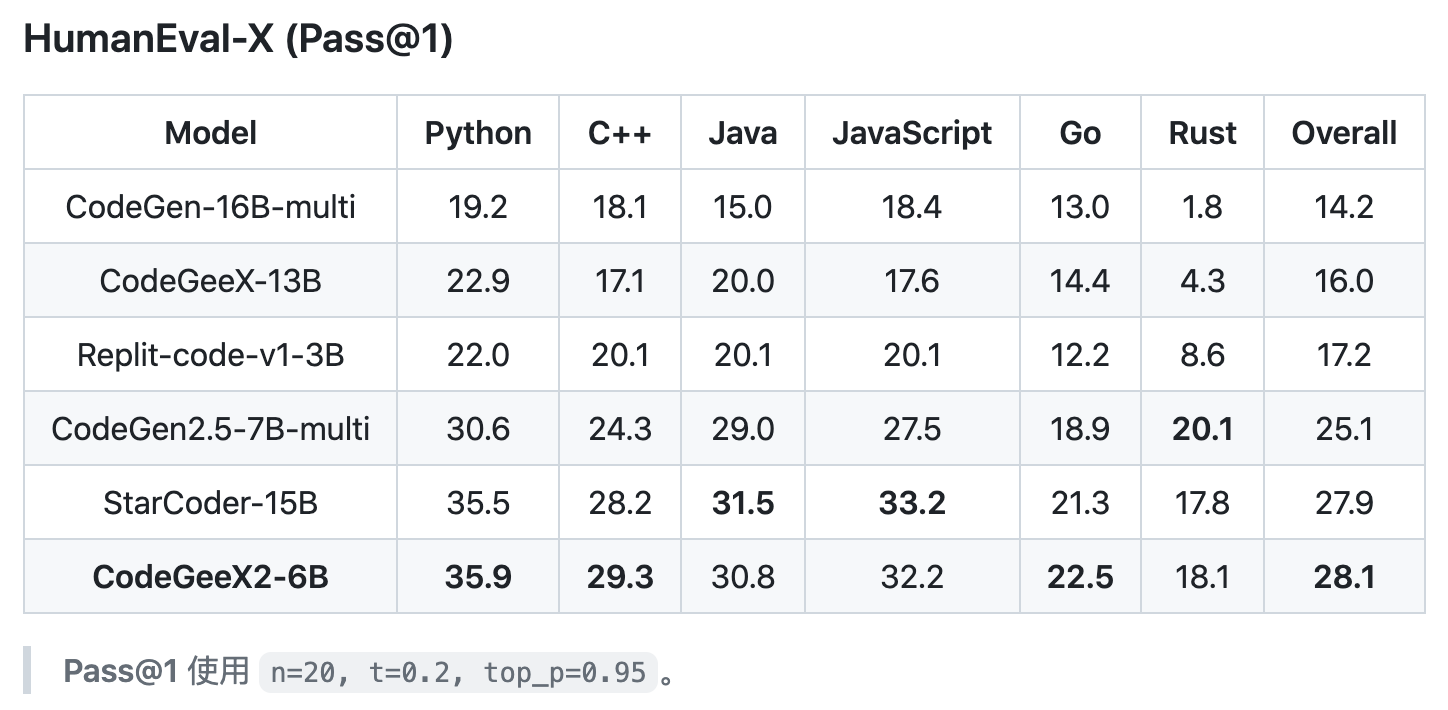
【论文】智源CodeGeeX + HumanEval评测集_humanevalx-CSDN博客
Paper page - Qiskit HumanEval: An Evaluation Benchmark For Quantum Code ...
End-to-End Secure Evaluation of Code Generation Models | Databricks Blog
iRAT: Improved Retrieval-Augmented Thinking for Context-Aware ...
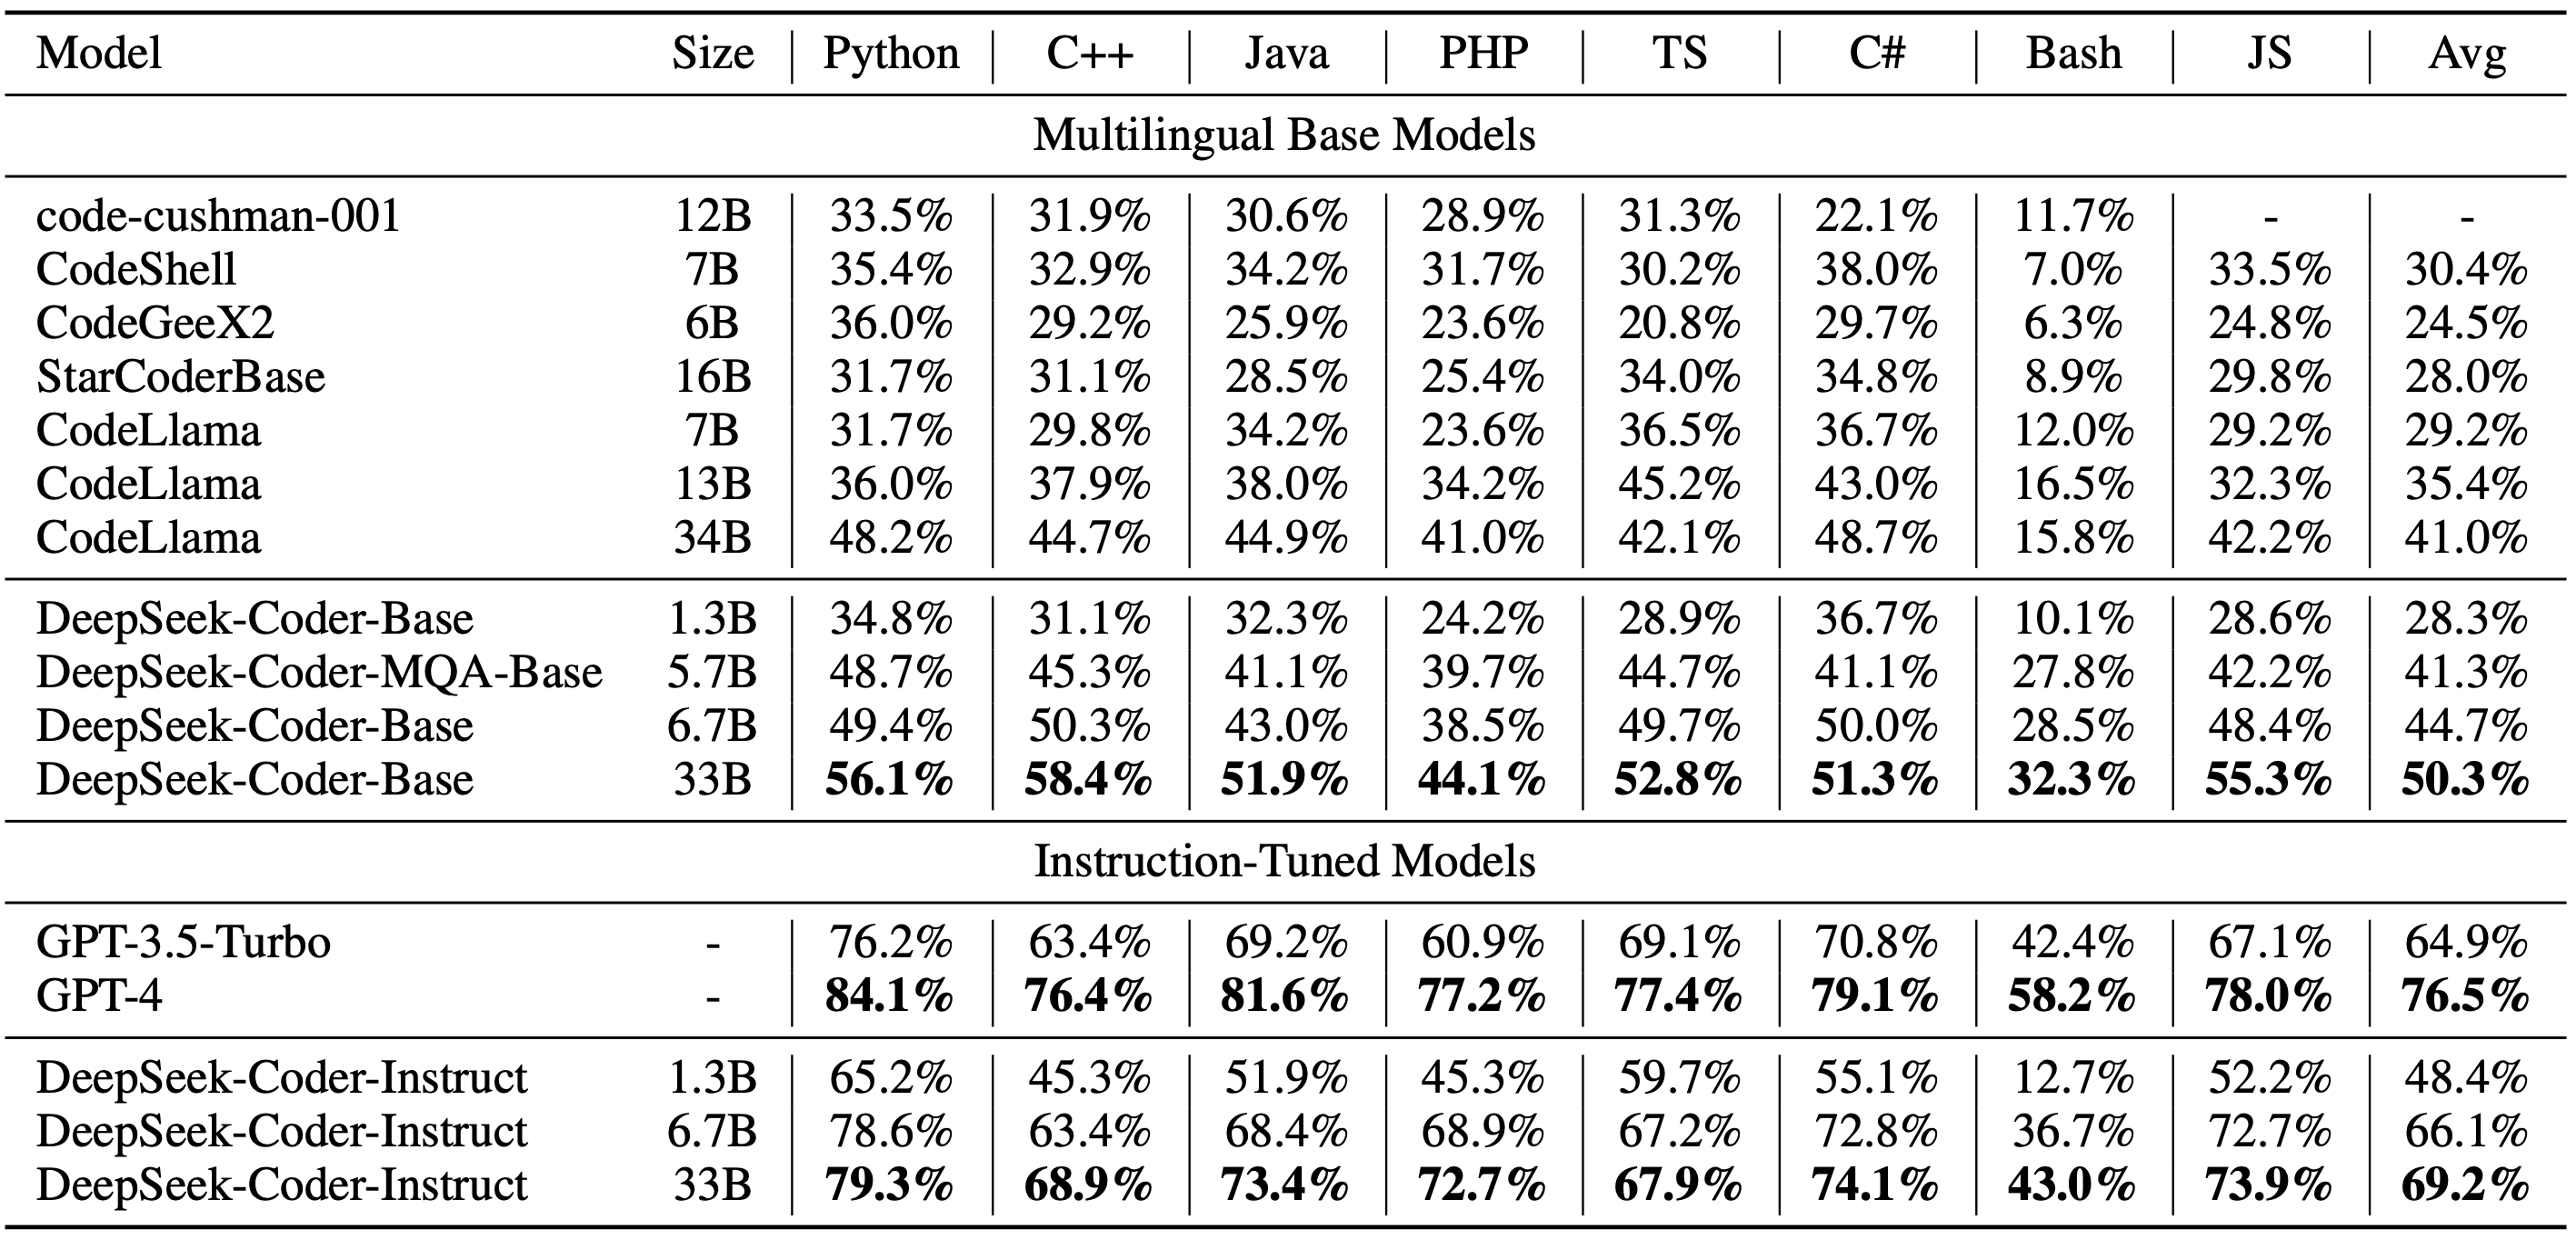
DeepSeek Coder
Figure 2 from PoseGPT: Quantization-based 3D Human Motion Generation ...
Building and Training Large Language Models for Code – Quantum™ Ai Labs
Qiskit HumanEval: An Evaluation Benchmark For Quantum Code Generative ...
neuralmagic/quantized-llama-3.1-humaneval-evals · Datasets at Hugging Face
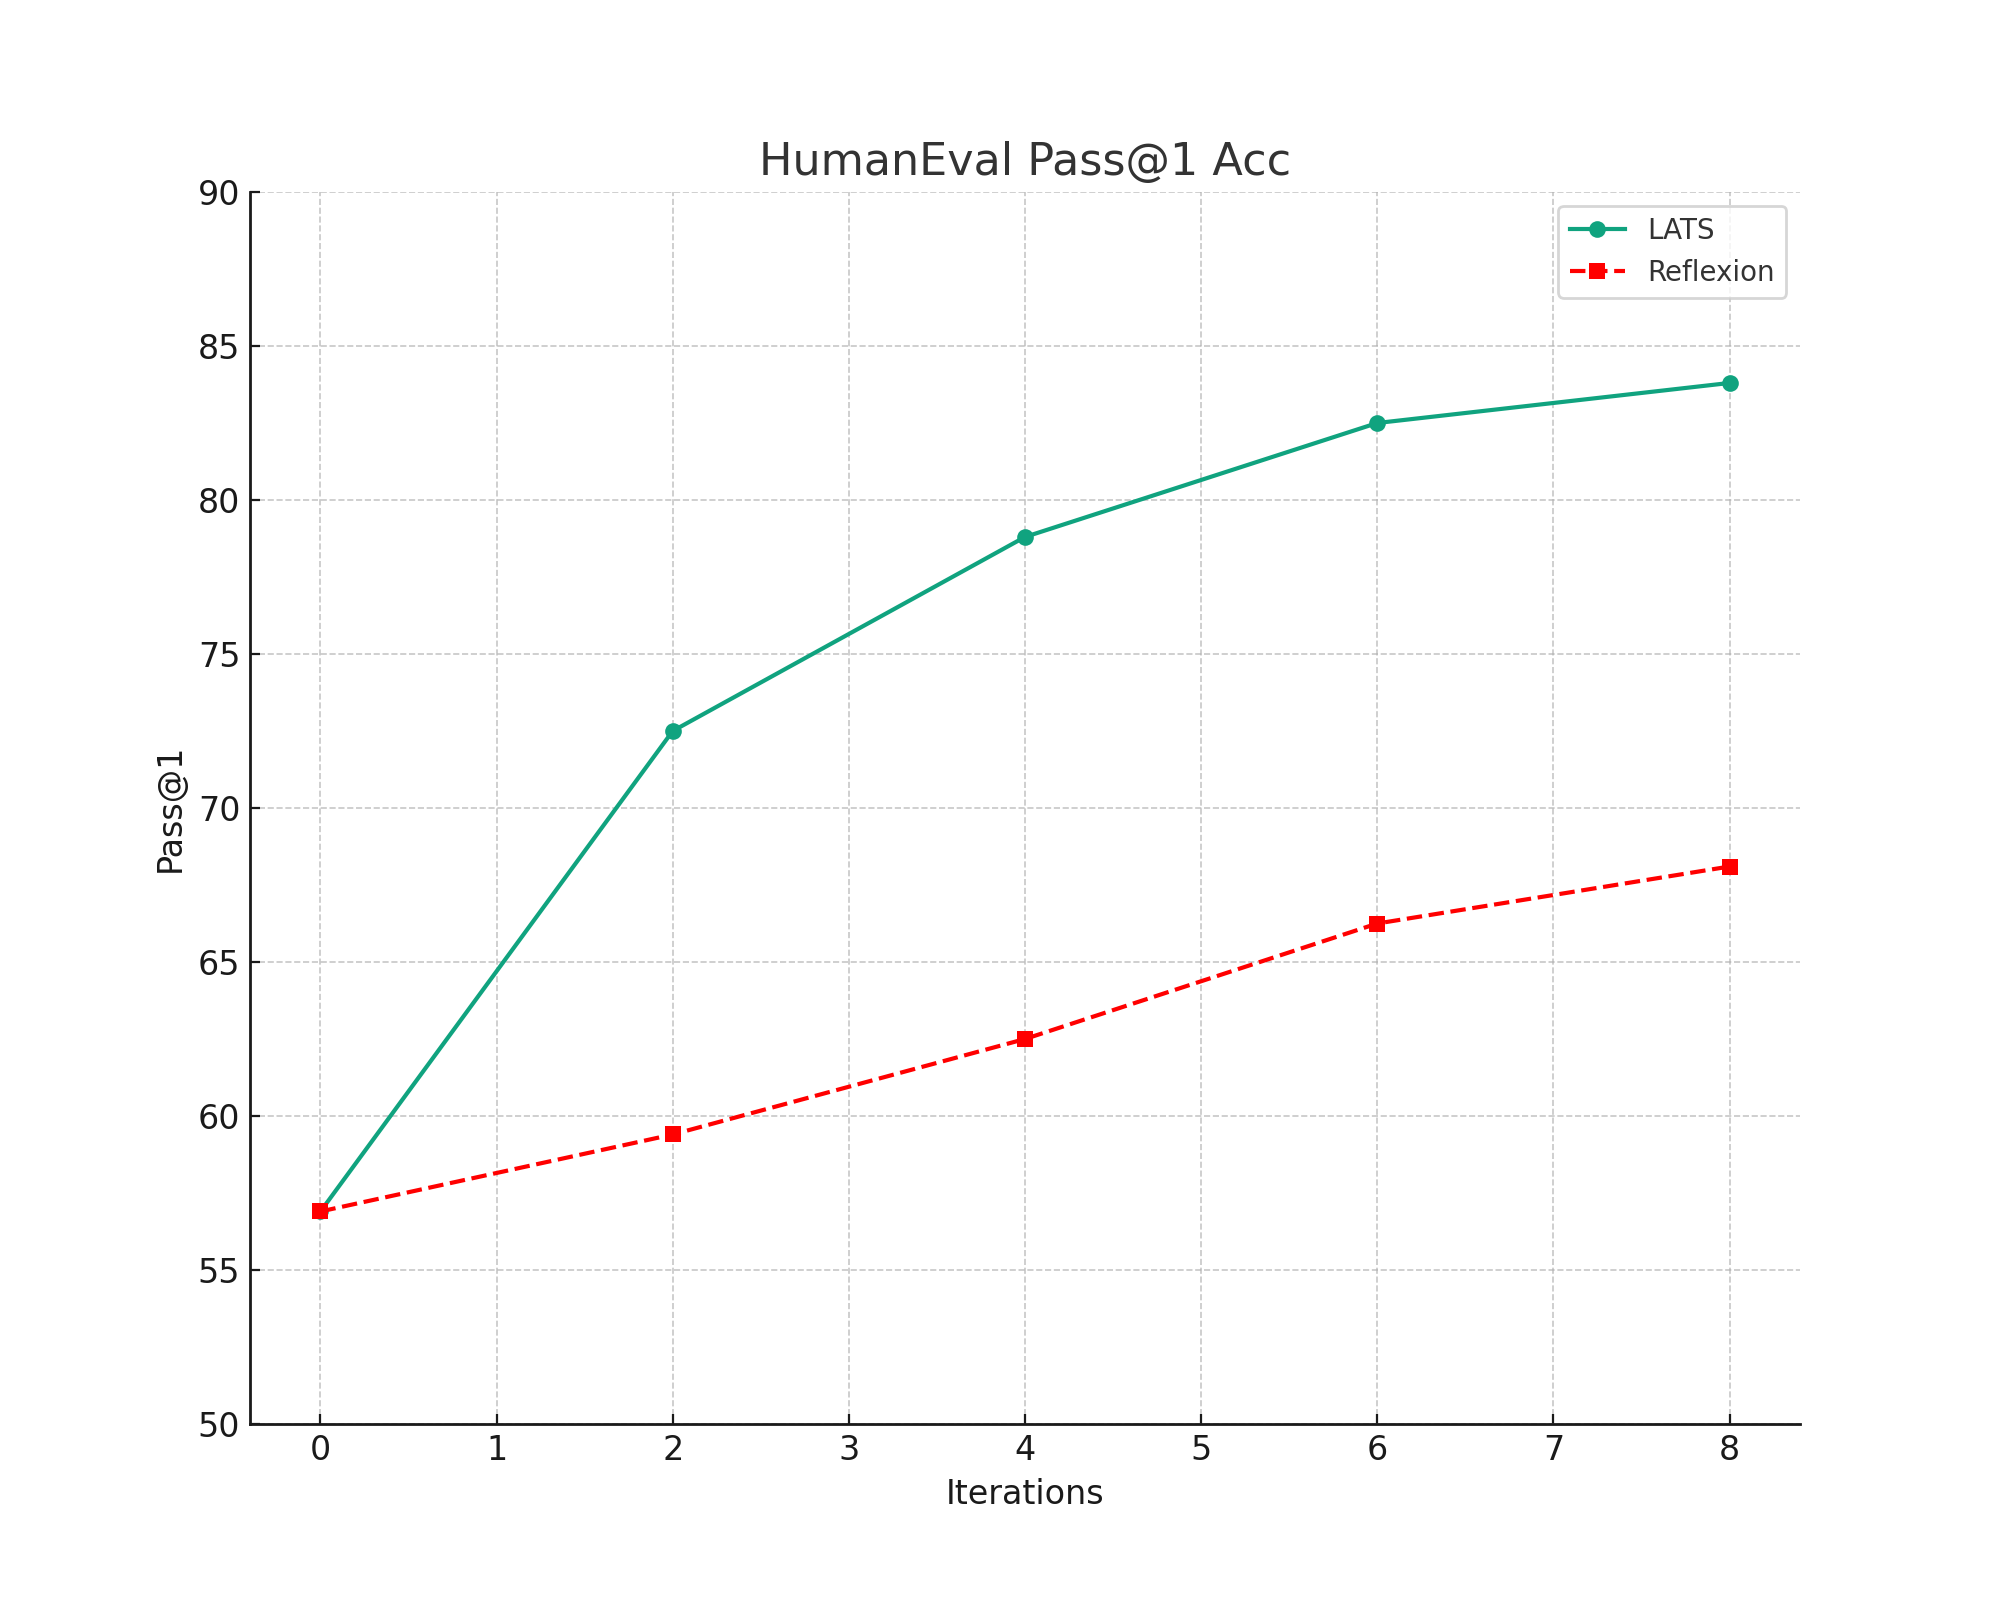
[2310.04406] Language Agent Tree Search Unifies Reasoning Acting and ...
LLM code gen
HumanEval: A Benchmark for Evaluating LLM Code Generation Capabilities ...
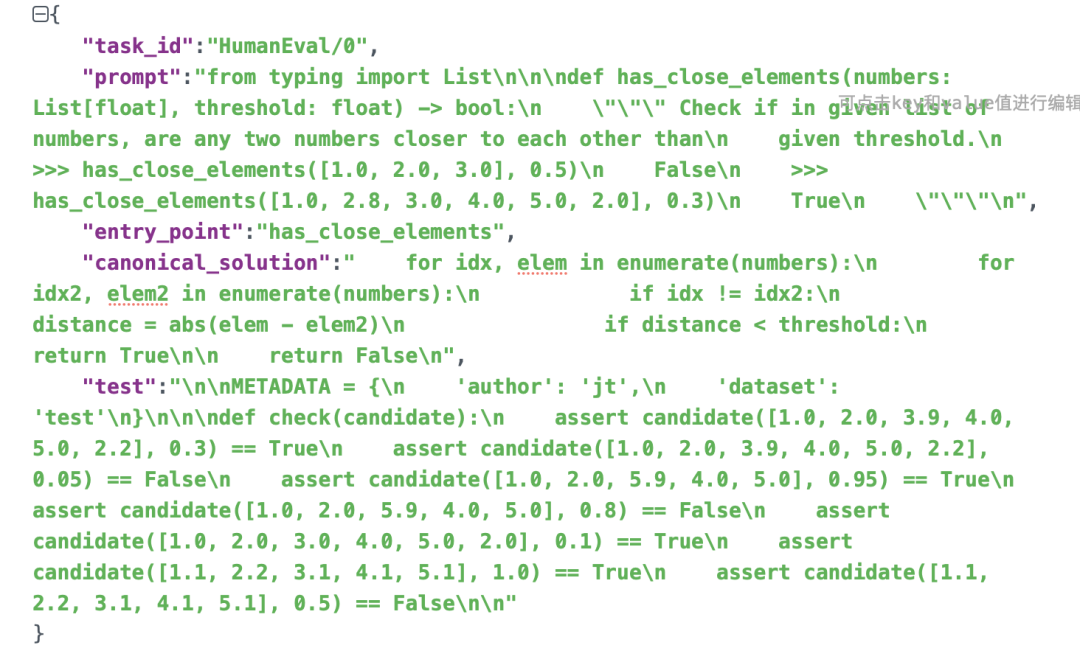
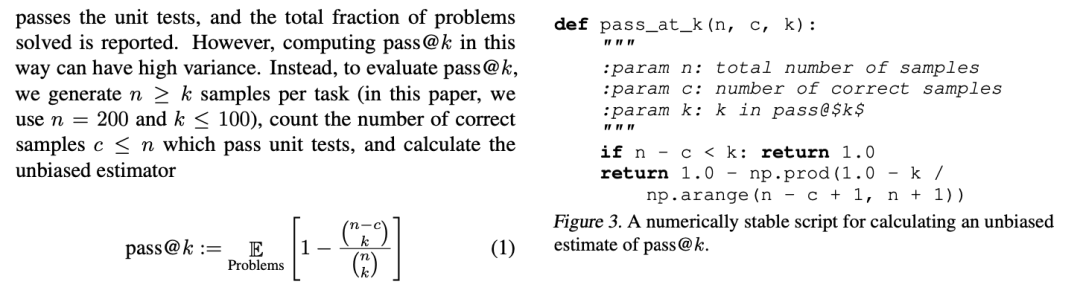
HumanEval是如何进行代码评估的:从数据构成、评估逻辑到pass@k指标计算 - 智源社区
[2404.01903] Activation Steering for Robust Type Prediction in CodeLLMs
HumanEval: LLM Benchmark for Code Generation
[2501.09316] SOP-Agent: Empower General Purpose AI Agent with Domain ...
Riddhi More | AI/ML Developer & Researcher
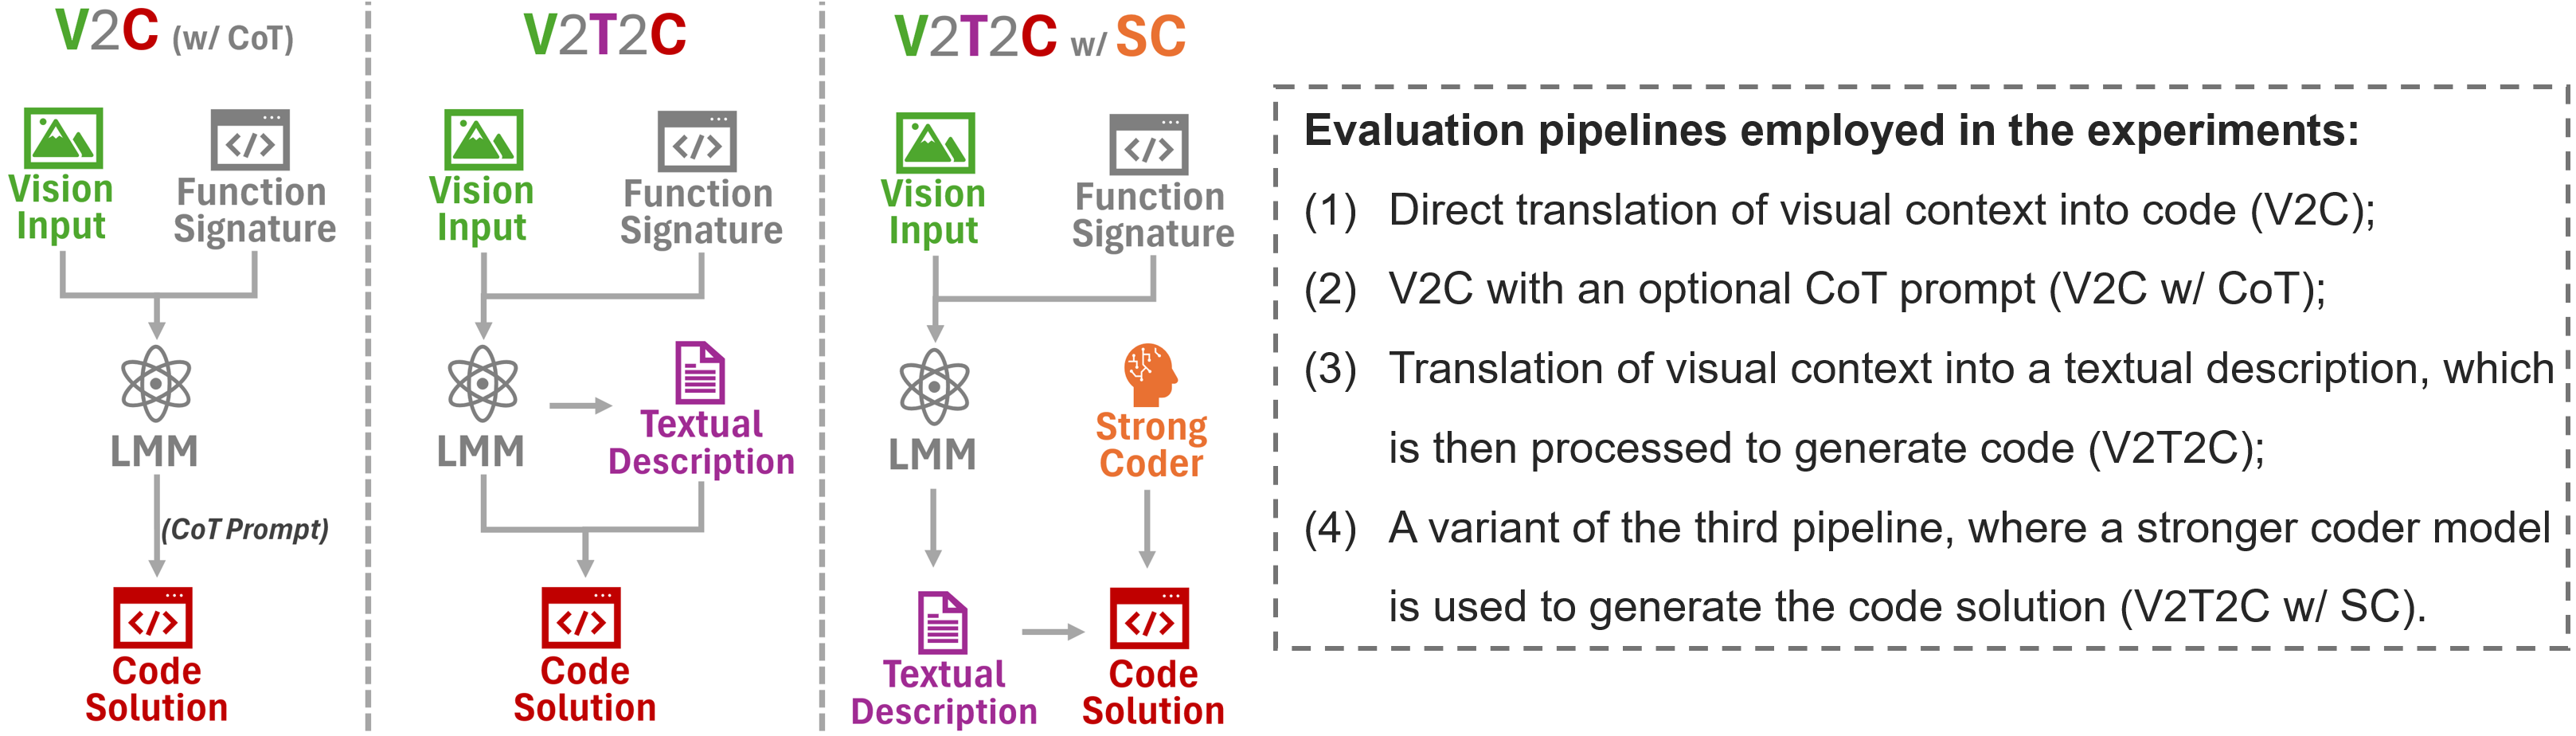
HumanEval-V: Evaluating Visual Understanding and Reasoning Abilities of ...
HumanEval是如何进行代码评估的:从数据构成、评估逻辑到pass@k指标计算-CSDN博客
HumanEval.org - AI Performaces, Human Evaluations
LLM量化效果评估:50万次实测后的发现 - 智源社区
GitHub - HumanEval-V/HumanEval-V-Benchmark: A Lightweight Visual ...
Model Quantization: Run Large AI Models on Limited Hardware
HumanEval-XL: A Multilingual Code Generation Benchmark for Cross ...
Training Language Models with Textbook-Quality Synthetic Data | Towards ...
Code-vision: Evaluating Multimodal LLMs Logic Understanding and ...
(PDF) PoseGPT: Quantization-based 3D Human Motion Generation and ...
Paper page - HumanEval-V: Evaluating Visual Understanding and Reasoning ...
Neural Magic 发布 quantized-llama-3.1-humaneval-evals 数据集, 应用在 模型评估、量化技术 领域
How to Evaluate LLMs: HumanEval, MMLU, TruthfulQA Explained
HumanEval-X - Alpha Hinex's Blog
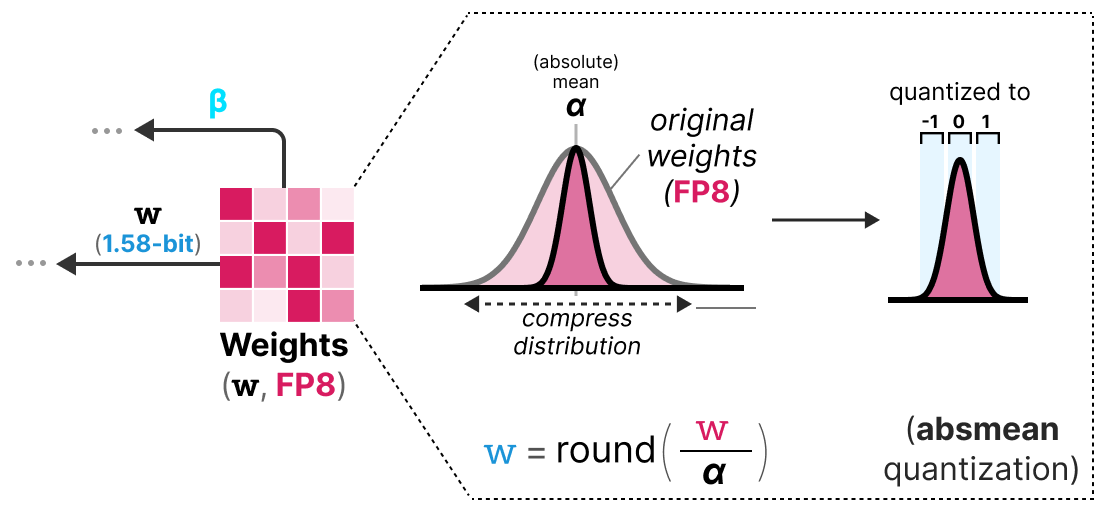
BitsFusion
GitHub - chateval/scale-based-human-eval: All experiments and ...
大模型代码评估:pass@k的推导和计算 - 知乎
Context-Guided Decompilation: A Step Towards Re-executability
Evaluating Large Language Models Trained on Code - 知乎
从HumanEval到CoderEval: 你的代码生成模型真的work吗? - 知乎
Aman's AI Journal • Primers • Agents
Evaluation & Datasets — State of Open Source AI Book
Introduction to Medical Imaging Applications | PPTX
Understanding AI/LLM Quantisation Through Interactive Visualisations ...
Benchmark of LLMs (Part 3): HumanEval, OpenAI Evals, Chatbot Arena | by ...
25 AI benchmarks: examples of AI models evaluation
test-gen/code_humaneval_qwen2.5-7b_t1.0_n8_tests_humaneval_o4-mini_t0 ...
Small Model results on Human Eval and MBPP. | Download Scientific Diagram
human-eval/human_eval/__init__.py at master · openai/human-eval · GitHub
Qiskit HumanEval|量子计算数据集|编程评估数据集
Attn-QAT: 4-Bit Attention With Quantization-Aware Training
Qualitative visualization on four different actions of the HumanEva and ...
Figure 1 from Evaluation of Compressed Images Based on Human Visual ...
【论文阅读】PoseGPT: Quantization-based 3D Human Motion Generation and ...
GitHub - evalplus/humanevalplus_release: Release repository for ...
Rewriting Pre-Training Data Boosts LLM Performance in Math and Code
Model performance on MultiPL-HumanEval by language frequency and ...
GlotEval-HumanEval documentation — GlotEval-HumanEval documentation
LLM Benchmarks: Understanding Language Model Performance
大模型入门指南 - Quantization:小白也能看懂的“模型量化”全解析_深度学习quantization-CSDN博客
Lecture 5 - ADC (Analog-to-Digital Conversion - HVL - ELE201 ...
使用教科书级质量的合成数据训练语言模型 - 小猪AI
Adaptive Graph Pruning for Multi-Agent Communication
[2310.03533] Large Language Models for Software Engineering: Survey and ...